What Are RSS Readers and How Do They Work

You open a favorite blog, check an industry publication, scan a news site, and search a few specialist pages for fresh articles. Then you repeat the process later because none of those sites tells you clearly what changed. The work isn't difficult, but it fragments your attention and makes it easy to miss something useful.

RSS readers solve that problem by bringing new items from selected websites into one interface. Instead of visiting every homepage, you subscribe to a site's machine-readable feed and let the reader collect updates for you. The result is a personal, algorithm-free information dashboard, built from sources you chose rather than recommendations selected by a social platform.

Table of Contents

The Core Purpose of RSS Readers

A site owner publishes a new article, and a reader wants to receive it without relying on a social platform, email list, or repeated visits to the homepage. RSS connects those two needs. The publisher exposes a feed once, while the reader subscribes through software that collects new items in a usable stream.

An RSS reader therefore works like a personalized newsstand. You choose the publications, decide which sources belong in the collection, and usually read updates in chronological order. The software retrieves items made available by your selected feeds, rather than ranking them according to predicted engagement.

From repeated checking to one dashboard

RSS is an XML-based method for syndicating content. A publisher exposes a feed, and reader software checks it periodically, gathers newly available items, and presents them together. Depending on what the publisher provides, the reader may display a headline, summary, date, and link while the full article remains on the original website.

That separation gives readers practical control over their information flow. A small independent blog can sit beside a large publication without either site's navigation determining how you find its updates. You can also remove a source when it becomes noisy, irrelevant, or unreliable.

Practical rule: Subscribe to sources because you value their publishing, not because you feel obliged to keep up with them.

RSS became important during the early web's shift toward automated content distribution. By late 2004, approximately 5% of U.S. internet users, more than 5 million people, reported using an RSS or XML reader for blogs and other content-rich websites, according to Pew Internet's survey of RSS audiences. The same research estimated that about 6 million Americans received news and information through RSS aggregators, while a separate May to June 2005 survey found that only 9% of internet users said they understood RSS feeds well.

These figures show that RSS had practical users before it became widely understood. The same remains true now. You can subscribe to a feed without learning XML, just as you can open a web page without studying how a browser processes it.

RSS also supports publishing workflows beyond personal reading. An automation specialist might turn RSS feeds into avatar videos, connecting newly published items with later production steps. The feed remains an open delivery layer that any compatible tool can consume, which supports interoperability between publishers, readers, and automated services.

RSS readers may be free to use, but their privacy, storage, synchronization, filtering, and export behavior can differ considerably, so apply the same scrutiny you would to any tool. For publishers, maintaining a usable feed keeps distribution available across reader software and other services, giving audiences a direct route to updates beyond a single platform.

How Feed Aggregation Actually Works

An RSS reader usually performs a quiet sequence of operations. It retrieves an XML document from a publisher, finds the feed's top-level <rss> element and <channel>, reads the individual <item> records, and turns those records into a readable stream.

You don't need to edit XML to understand the model. Think of the feed as a structured bulletin. The channel describes the publication, while each item describes one update.
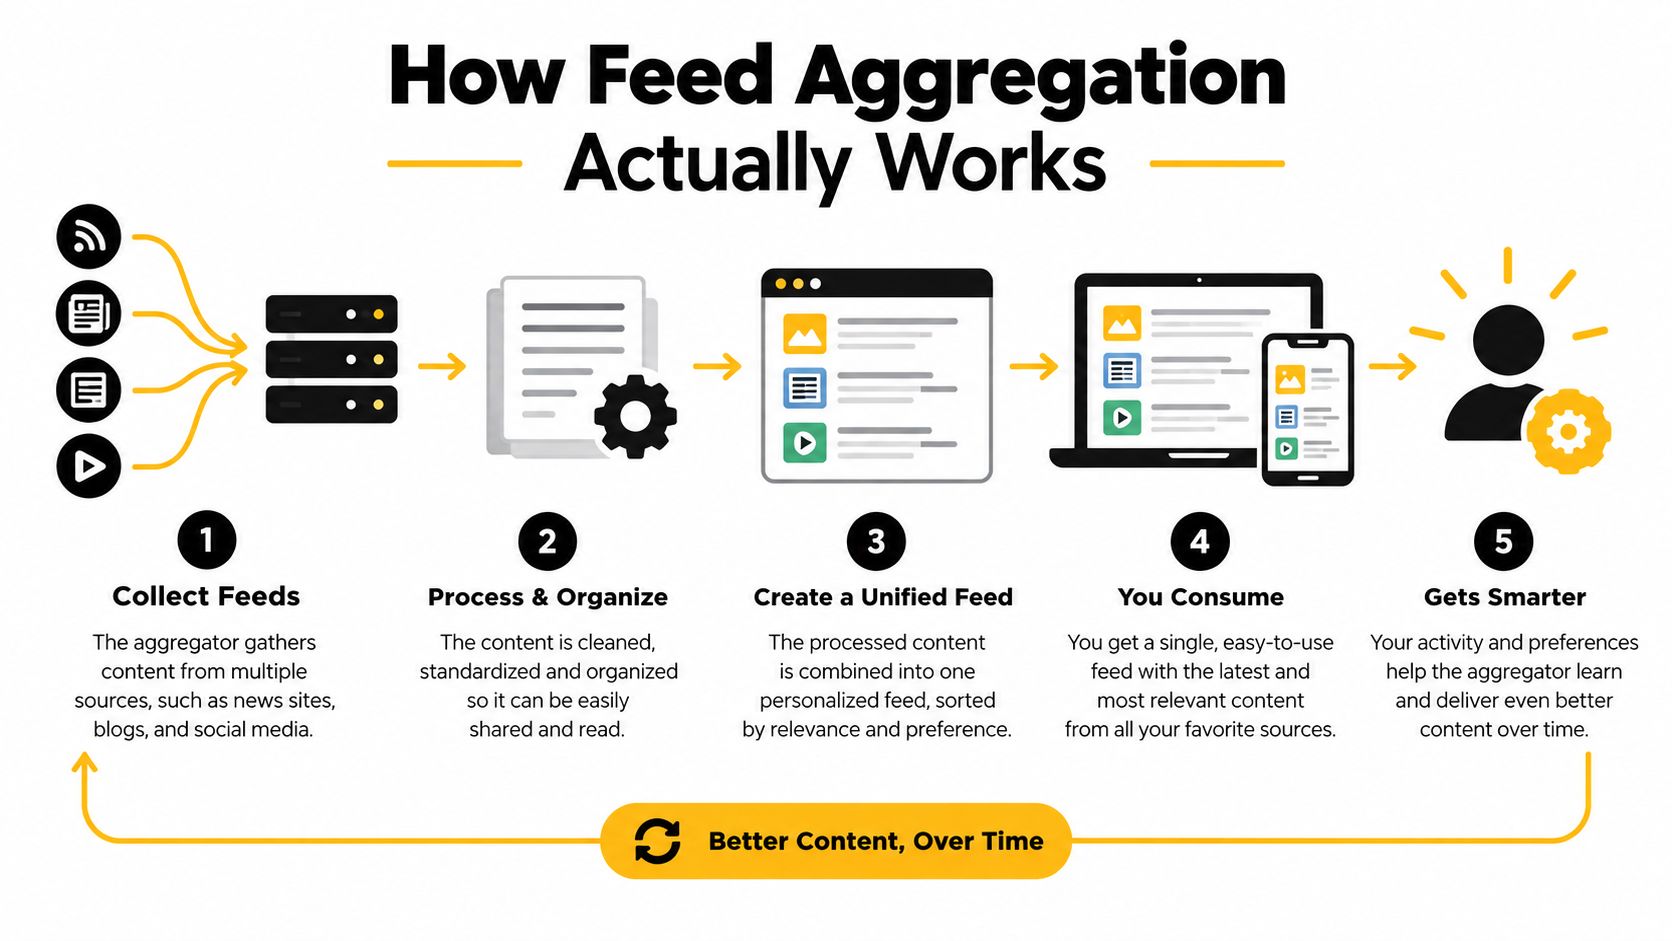
A diagram illustrating the five-step process of how feed aggregation technology collects and organizes online content.

What an RSS item contains

Under RSS 2.0, a channel holds feed-level information, and an item represents a discrete update such as an article or blog post. An item must include at least a title or description. It may also include a canonical link, publication date, author, categories, comments URL, enclosure, and globally identifying GUID.

The RSS specification draft describes this structure and its role in syndication. A reader may immediately display the title, summary, date, and source, then send you to the publisher's page when the feed provides only an excerpt.

The GUID, or globally unique identifier, helps a reader distinguish a new item from an edited or reordered one. Stable identifiers matter because a publisher might change the order of posts, update an article, or redesign the site. If the identifier changes unnecessarily, the reader may treat an old item as new and create a duplicate.

Discovery and retrieval are different jobs

A feed reader isn't normally a permanent copy of the website. It periodically retrieves the XML feed and stores or displays the information its design supports. The feed might contain a complete article, a short excerpt, an image reference, or only a link.

Consider a WordPress site with a site-wide feed at /feed/. A desktop application, mobile reader, browser service, or automation tool can subscribe to that endpoint without requiring a special app made by the publisher. The reader discovers the update through the feed, while your browser retrieves the full page from the original site when you open the link.

That interoperability is useful for publishers and operators. A content team might auto-tweet blog posts after a new item appears, while a reader might use the same feed only for personal research. The feed doesn't dictate one destination. It gives different tools a shared way to receive structured updates.

For a practical WordPress example, Read More Info's blog shows the kind of publication archive that can be followed through standard site syndication. The reader doesn't need to know whether the publisher uses a simple theme or a complex editorial workflow. It needs a feed that follows the expected structure.

RSS files must conform to XML 1.0. Malformed nesting, unescaped ampersands, invalid encoding, or unclosed elements can cause a parser to reject the document instead of skipping only the damaged post. A reader that appears to have missed an article may therefore be dealing with a feed error, a polling interval, or a retention rule rather than a failure to publish.

The following video provides another visual explanation of how feed aggregation connects a publisher's updates with reader software.

Choosing the Right Reader for Your Workflow

A publisher checking feeds on a laptop in the morning and a phone later needs more than a pleasant interface. The right RSS reader depends on where you read, how much control you want, and whether subscriptions, unread items, and saved articles should follow you across devices. The main options are cloud-hosted readers, local desktop or mobile apps, and self-hosted software.

A cloud reader works like a shared mailbox for feeds. The service stores your account and synchronizes subscriptions, unread items, and saved articles across devices. That convenience supports an algorithm-free reading routine, because you choose which sources appear and in what order. The trade-off is data exposure. Depending on the provider's design and policies, it may record account details, reading activity, IP addresses, or synchronization events.

A local reader keeps more of its operation on your own device. It can provide stronger offline access and reduce reliance on a third party, although synchronization between devices may be limited or require extra configuration. A device failure can also create a recovery problem if you have not exported your subscriptions.

Self-hosted software places the server, storage, and update process under your control. It fits readers who can maintain their own installation and want less dependence on a commercial service. You also take responsibility for backups, updates, security, and availability. The reader remains open and adaptable, but only while someone keeps the installation working.

RSS Reader Categories Compared

Reader TypePrivacy LevelCross-Device SyncSetup Complexity
Cloud-hosted serviceDepends on the provider's data practicesUsually convenientLow
Local desktop or mobile appOften stronger local controlMay be limited or device-specificLow to moderate
Self-hosted solutionHigh control if maintained carefullyAvailable when configuredModerate to high

Test the workflow before judging the interface. Export support matters because an OPML file lets you back up and move a subscription list. Check whether the reader offers folders, filtering, mute rules, full-text retrieval, offline reading, and dependable read-state tracking. Open an original article as well. The transition should preserve your place and make clear which site published the item.

Ownership check: Your subscription list is valuable editorial data. Choose a reader that lets you export it before you build a large collection.

Privacy needs the same practical examination. A local or self-hosted reader can reduce third-party exposure, while a hosted service may provide easier synchronization at the cost of retaining more operational data. Compare the provider's stated behavior with the control you need. Judge a reader the way you would judge any free software: by its export format, privacy policy, and maintenance cost, not by its price tag.

For WordPress site owners, the reader shapes how visitors experience a publication beyond its website. A clear feed, predictable links, and sensible excerpts make subscriptions useful across hosted, local, and self-managed readers. Site design still affects whether visitors can find and understand that content, so WordPress blog layout guidance belongs in the same publishing plan as the feed endpoint.

Navigating Broken Feeds and Incomplete Data

RSS is a delivery layer, not a guaranteed archive. A reader doesn't usually store a canonical copy of every page, and it can't repair information that a publisher never placed in the feed. If a feed contains only excerpts, the reader may show only excerpts. If the publisher removes the endpoint, the subscription can become stale.

This distinction prevents a common misunderstanding. A reader can tell you that an item was published, but it may not preserve the complete article, images, comments, or formatting. Government guidance on RSS explains that readers regularly check subscribed feeds and download updates, so missed items can result from polling intervals, feed errors, or retention limits. The U.S. Courts RSS frequently asked questions provides useful background on that subscription model.

Diagnose the failure before changing readers

Start with the feed address. Open it in a browser or feed validation tool and check whether it returns XML rather than an error page, login screen, or HTML template. If the publisher has redesigned the site, the old address may redirect, return an empty document, or expose a new endpoint.

Use this checklist when updates stop appearing:

  • Check the endpoint: Confirm that the feed address still loads and that the publisher hasn't moved it.
  • Inspect recent dates: A feed with no recent publication dates may be stale, even if the reader still shows old items.
  • Look for duplicates: A redesign or changed GUID values can make existing posts appear as new. Remove duplicates carefully rather than deleting the whole subscription.
  • Test the original link: An item can appear in the reader while its canonical page has moved or broken.
  • Compare full text and excerpts: Publisher settings determine whether the feed exposes a complete article, a summary, images, or only a link.
  • Validate the XML: Unescaped ampersands, invalid encoding, broken nesting, and unclosed elements can stop parsing.
  • Export subscriptions: Keep an OPML backup so a reader migration or service failure doesn't erase your carefully selected sources.

Know what the reader can't fix

A feed reader may use the GUID to identify an item, but it can't infer the correct identity when a publisher changes identifiers carelessly. It may also retain only a limited history, depending on the application. A missed post might never reappear after the reader's retention window passes.

The practical response is to combine feed reading with browser reading. Use the reader for discovery and triage, open the canonical page for full context, and keep important material in a separate archive or notes system. That workflow respects the publisher's delivery choices without pretending that RSS replaces the website.

The same caution applies to automation. A workflow built on a feed should handle empty results, duplicates, redirects, and malformed XML. Treat the feed as an input that needs monitoring, not as an infallible database.

Curation Strategies for Information Overload

An algorithm-free stream gives you control over selection, but it does not remove the problem of volume. Subscribe to too many high-output sources and your reader becomes another crowded inbox. Chronological order places every update beside the next, even when one item deserves careful attention and another can wait.

Deliberate curation keeps the collection useful. Start with a clear question: What decision, project, or interest does this feed support? If you cannot answer, leave the source outside your main collection until its purpose becomes clear. RSS works best as a chosen information layer, not a second copy of the entire web.

Build a reading system you can maintain

Use folders based on real tasks rather than broad labels such as “interesting.” A publisher might create folders for client research, industry news, technical reference, local updates, and long-form reading. The structure works like labeled trays on a desk. Each folder narrows the next decision, so you spend less time deciding what to open.

Apply these controls as the collection grows:

  1. Separate urgency from importance. Put time-sensitive sources in one folder and reflective or evergreen sources in another.
  2. Mute repetitive topics. If a feed publishes frequent variations on the same subject, use keyword rules where the reader supports them.
  3. Filter before saving. Save items connected to a current project instead of treating every unread headline as future research.
  4. Review low-value feeds. Remove sources that create more noise than insight. You can always resubscribe later.
  5. Use a holding area. Keep experimental subscriptions away from the feeds you read every day.

Editorial discipline: An unread count is not a responsibility. It only measures the items your reader has retrieved.

Curation also requires accepting the limits of a chronological feed. It will not automatically balance subject areas, identify the most important story, or supply every piece of context. Its strength is transparency: you can see which source published an item and why it entered your collection. Use tags, folders, and saved items to add your own priorities without surrendering selection to an opaque ranking system.

The same discipline applies to free tools in general. Google Cloud's free AI tools information, for example, documents concrete allowances, including the first 1,000 units per month for Cloud Vision and the first 1,000 minutes of analyzed video per month for Video Intelligence at no charge. Those allowances do not expire, although Google says limits may change. That level of specificity is useful when trimming a feed list: evaluate stated conditions rather than vague labels.

One documented video-tool comparison shows a 720p output limit and one watermark-free export per month on one free tier, versus unlimited 1080p exports without a watermark elsewhere, so inspect actual conditions before committing, as explained in this free AI video-editing comparison.

Keep the same standard for any service you follow or recommend. Check file compatibility, export restrictions, privacy terms, quotas, and whether a product is free or only a trial. Curation includes the sources in your reader and the tools you use to process what they deliver.

Why Open Feeds Matter for Modern Publishers

For a publisher, an RSS feed is a distribution contract. It tells readers and other software how to discover new work without forcing them into a proprietary application or a social platform. A clean feed can reach a desktop reader, mobile app, browser service, newsletter workflow, accessibility tool, or internal automation process.

That interoperability changes the relationship between publisher and audience. A social platform may decide which followers see a post, while an RSS subscriber intentionally selects the source. The publisher still needs to earn attention through useful work, but the delivery path doesn't depend entirely on an engagement ranking system.

Treat the feed as part of the publication

A reliable publishing setup starts with a stable site feed and clear canonical links. Check whether titles, summaries, dates, authorship, categories, and GUIDs appear consistently. Decide whether readers should receive complete posts or excerpts, then communicate that choice through the site's design and the destination page.

Comments feeds can extend the relationship beyond new articles. Sites like Read More Info expose open site and comments RSS feeds, allowing readers to follow new posts or discussions through automation workflows and supporting publishers who value open syndication over app-specific engagement loops.

The publisher should also protect the subscription experience during changes. Keep feed addresses stable where possible, preserve redirects when an endpoint moves, validate XML after theme or plugin changes, and maintain a backup of important configuration. A feed that works today but breaks after a redesign weakens trust, because subscribers may not realize that updates have stopped.
A modern laptop on a white desk displaying a content management dashboard with analytical growth charts.

Open syndication supports durable discovery

RSS doesn't replace a website, newsletter, search strategy, or social presence. It gives those channels a standards-based companion. A reader can discover a post through the feed, open the canonical page for the complete experience, search the site for related material, and return through the same subscription when the next update arrives.

That makes RSS especially useful for WordPress beginners and small publishers. You don't need to build a proprietary reading application to offer subscribers a structured way to follow your work. A well-maintained feed lets other tools participate while the original site remains the authoritative destination.

If you're building a publication, the feed should be planned alongside the site itself. This guide to creating a WordPress blog can help establish the broader publishing foundation, while feed validation and subscription testing protect the delivery layer.

Open feeds also clarify what the publisher owns. You may not control every reader application, but you can control the source URL, item structure, canonical links, publication rhythm, and quality of the original page. Readers choose how they consume the update, and publishers retain a direct path to the work.

In practical terms, RSS is neither a nostalgic inbox nor a complete archive. It's an open, algorithm-free mechanism for moving structured updates from a publisher to the tools a reader trusts. Its value depends on thoughtful subscriptions on one side and dependable feed maintenance on the other.


Read More Info offers a straightforward WordPress publication with informational posts, site-wide RSS syndication, comments feeds, search, and a mobile-friendly reading experience. Visit Read More Info to explore the site and follow its updates through the RSS reader that fits your workflow.
Responsive Design Testing Across Devices and Viewports

You've got the desktop version looking polished, the homepage hero finally lines up, and then a client opens the same page on a phone and the header jumps, the button text wraps badly, and a scrollbar appears where no one expected it. That's the moment responsive design testing stops feeling like polish work and starts feeling like damage control. If your site has already reached that point, the fix isn't more guessing, it's a better testing matrix, better tooling, and a clearer idea of which failures matter most.

Table of Contents

Why Responsive Design Testing Became Non-Negotiable

A mobile review can fail on a detail that looked harmless during development. A headline clips by a few pixels, a menu closes late, or two tap targets sit too close together. Those defects often appear at the point where a visitor decides whether to continue, leave, or complete an action.

The shift happened because the web no longer serves a desktop-first audience by default. Mobile devices generated 54.4% of global website traffic at the end of 2021, 62.54% in Q2 2025, and about 63% in 2026, while one 2025 source reported 64.35% in July 2025 (HubSpot mobile optimization stats). The exact share varies by market and measurement period, but the testing requirement is consistent: a broken phone layout can affect the primary entry point to the site.

Practical rule: build your device matrix from analytics, then rank tests by the user actions and templates most exposed to failure.

Do not treat every viewport as equally important. Start with the screens, browsers, and operating systems used by visitors, then add representative widths and conditions that expose different layout classes. Prioritize actions such as opening navigation, submitting forms, reading content, using search, and completing checkout. This changes the question from “which breakpoints should we test?” to “which user actions fail under real conditions?”

Responsive design has also become the standard implementation pattern. In 2015, only 17% of websites used responsive design, while 21% used separate mobile URLs and 62% used neither approach. By 2025, industry summaries reported that 90% of all websites had implemented responsive design (DeviceAtlas). The result is a codebase that must hold together across phones, tablets, desktops, orientations, and intermediate widths.

An infographic illustrating three key reasons why responsive design testing is essential for modern websites.

Teams that still treat mobile as an afterthought can use a practical mobile-first layouts and CSS guide to reduce avoidable layout problems before formal testing begins.

The requirement extends beyond appearance. Google's mobile-first indexing rollout in 2018 reinforced the need to verify content, layout, interaction, accessibility, and performance on small screens. Browser emulators can reveal many visual defects, but they may miss touch behavior, keyboard focus, network delays, viewport changes, and device-specific rendering. Responsive testing therefore protects real user actions, not just the position of elements on a page.

Choosing the Right Devices and Viewports to Test

Testing every possible width is a trap. The problem isn't just phones, tablets, and desktops. It's the spread of orientations, safe areas, foldables, ultrawide screens, and browser chrome behavior that makes a single “mobile” test meaningless. One source even describes the space as having over 4 million possible browser-size combinations between 320×480 and 2048×2048 (QWE tutorial).

The useful move is to stop chasing every screen and start building a risk-based device matrix. Start with the devices your analytics show, then add a small benchmark set that catches the layout classes many teams miss. The usual widths still matter, especially 320px, 768px, and 1024px (Diffy responsive design testing), but they should anchor your plan, not define the whole thing.

A simple way to think about the matrix is template risk. Checkout, search, pricing, and article pages deserve the first pass because failures there usually carry the highest user cost. Secondary templates can wait until the core flows are stable. That triage approach is how small teams avoid spreading attention so thin that nothing gets tested well.

Testing LayerCatches WellCommon Blind Spots
Analytics-driven device matrixReal visitor screens, top browsers, priority templatesRare devices and orientations not seen in traffic
Standard breakpoint setCore reflow behavior at common widthsIn-between widths, weird interactions, foldables
Template triageHigh-impact pages like checkout and searchLong-tail pages and low-traffic components
Full device sweepPhysical behavior and browser quirksScale, time, and maintenance overhead

The best breakpoint planning resources still help, especially if they frame widths as part of a wider strategy. A useful example is planning responsive breakpoints, which is worth reading once you've decided what your actual test matrix needs to cover.

The question is not “what are all the screen sizes?” The question is “which screen sizes create the most business risk if they break?”

A quick note on process is worth keeping close. If you're building a WordPress publication, this guide to creating a WordPress blog is a useful internal reference point for how a site structure gets assembled before responsive QA begins. The page architecture matters because navigation, article templates, and sidebar behavior all influence what needs to be checked at each width.

Testing Responsive Layouts with Browser Dev Tools

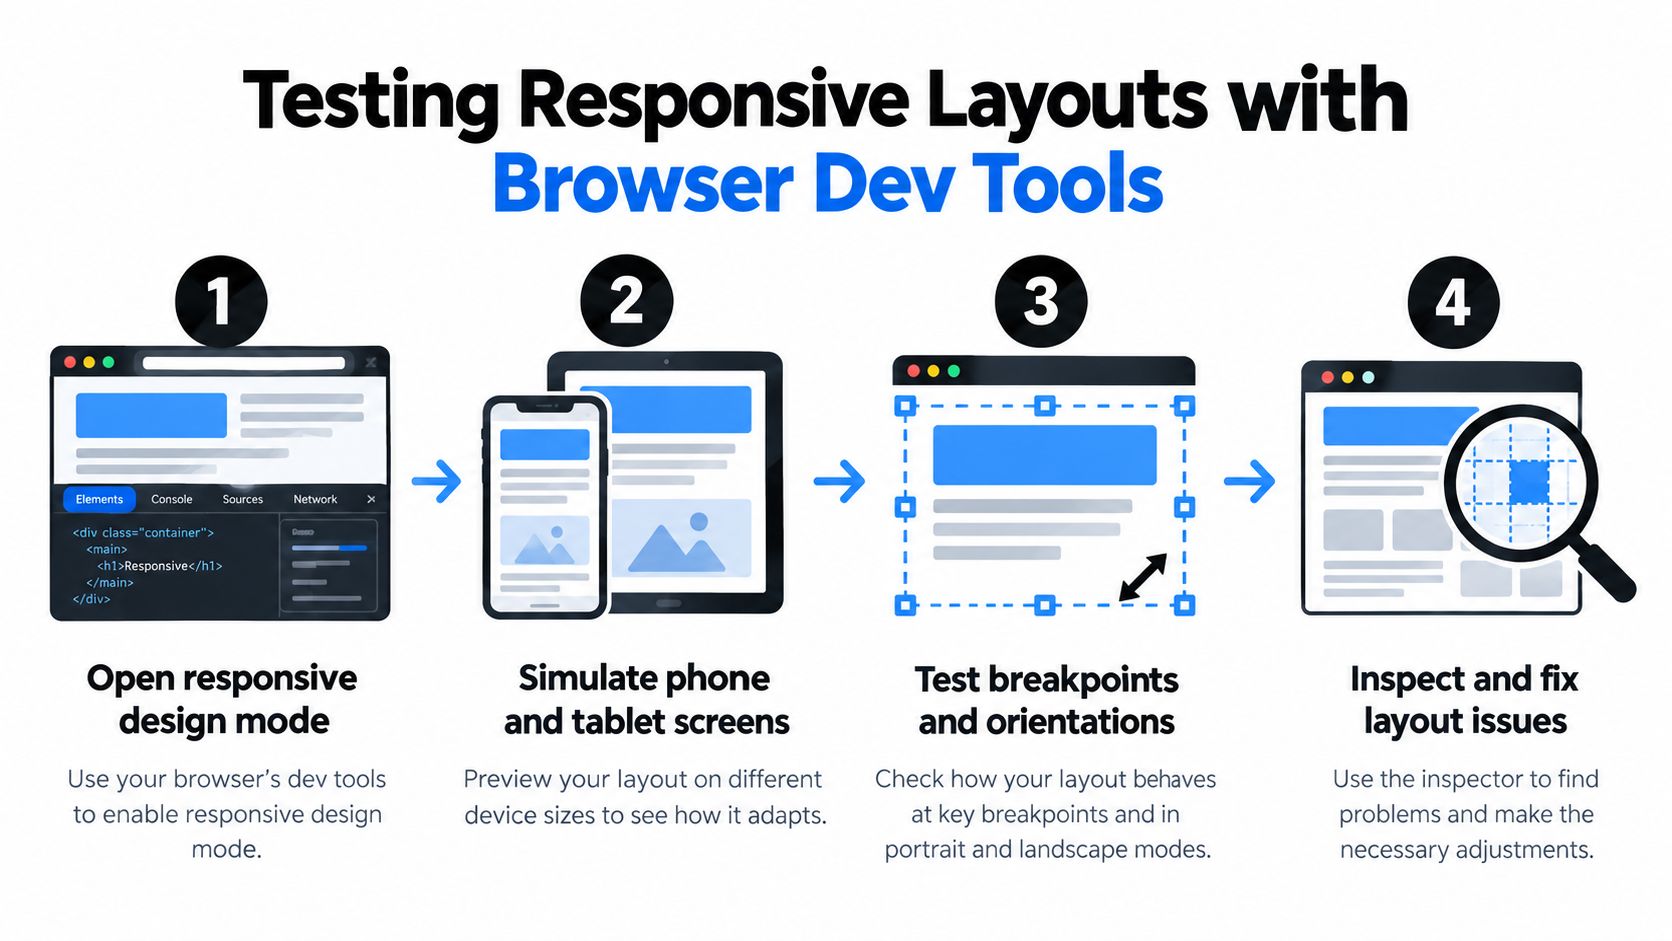
A layout can pass a desktop screenshot and still fail when a user opens the menu, enters a form field, or scrolls through a long article at an awkward width. Chrome DevTools gives you the fastest first pass. Open responsive design mode, choose a device preset, set a custom viewport, and inspect the critical template before reaching for a physical phone.

Use analytics to choose the first pages and widths, then test the actions that matter on those pages. A checkout, search form, article menu, or image gallery can fail even when the surrounding layout appears stable. The goal is not to chase every screen size. It is to find where real visitor tasks break.

An infographic showing four steps to test responsive website layouts using browser developer tools.

A practical DevTools workflow

  1. Open responsive mode and load a high-traffic template from your device matrix.
  2. Start at the narrowest relevant width, then increase it gradually instead of jumping straight to desktop.
  3. Drag the viewport slowly to expose flexbox edge cases, wrapping failures, fixed-width elements, and hidden overflow.
  4. Run the key user actions. Open menus, focus fields, submit forms, expand accordions, and move through keyboard focus.
  5. Throttle the network to check whether late images, scripts, or font swaps shift content or destabilize controls.

That sequence connects layout checks with interaction and performance checks. A page can remain visually intact while a menu becomes unreachable, a focused field moves off-screen, or content shifts after paint. DevTools exposes many of these defects before a real-device pass.

Template structure matters too. For layout patterns that hold up at every width, see our guide to the best WordPress blog layouts. Responsinator can provide a quick client-facing check by showing a live URL side by side across phone widths between DevTools passes. Chrome DevTools also includes responsive design mode for simulating phone and tablet screens directly from a computer (GoDaddy responsive testing tools).

Check screen matchMedia behavior when CSS or JavaScript depends on breakpoint-specific logic. Use verify screen matchmedia behavior to examine whether media-query conditions respond as expected while the viewport changes.

DevTools is fast and precise for structure, viewport changes, and scripted checks. It cannot reproduce every touch, browser-chrome, hardware, or connection condition. Use it to narrow the risk, then verify the highest-impact actions on real devices.

When Emulation Is Not Enough and Real Devices Take Over

Emulation is excellent for speed. It's weak at reality. A simulated phone screen can't fully reproduce touch behavior, browser chrome quirks, real-device DPI rendering, software-keyboard obstruction, hover-to-touch conversion, or how a page behaves under 400% zoom. Those are the bugs that look invisible on a laptop and annoying on a phone.

What real devices expose that emulators miss

On actual phones, the browser and the hardware interact in ways DevTools can't fake well. Tap targets that looked generous in simulation feel cramped with a thumb. A form field that seems fine on desktop may disappear behind the keyboard. A sticky header that works on a clean viewport can crowd safe-area insets or clash with device notches.

Recent guidance also calls out safe-area insets, mid-range Android hardware, and real 4G testing as necessary for surfacing issues that desktop tools miss (WebTonic responsive web design). That aligns with the practical experience teams have after a few painful launches, emulators are useful, but they're not enough for final sign-off.

Real-device verification should focus on actions, not just layouts. Can a user tap, type, scroll, zoom, and recover from interruptions without friction?

A strong real-device pass should include keyboard-only checks and throttled mobile audits. That matters because accessibility failures and performance failures often show up together on phones. If a menu is reachable only by hover, or a popover blocks the input the user needs next, the layout is technically present and practically broken.

The best rule is straightforward. Use emulation for early layout triage, then confirm critical pages on actual iOS and Android devices before release. If the page includes forms, filters, or dynamic navigation, the device pass isn't optional. It's the only layer that can tell you whether the experience still works under real fingers and real latency.

Automating Responsive Checks Without Losing Coverage

Manual testing cannot protect every commit. Automation keeps responsive checks running between releases, while human review handles the failures scripts cannot interpret. Build the suite around user risk, using analytics to identify the devices, templates, and actions that matter instead of chasing every possible screen size.

Visual regression tools work well when they run against critical templates at selected viewport sizes. They catch unexpected spacing changes, altered grids, and components that shift after a CSS or markup update. Screenshot checks remain limited, though. A pixel difference may be harmless, while a state-dependent bug, keyboard obstruction, or failed touch target may leave the image looking correct.

Use automation to test layout relationships and visibility rules alongside screenshots. Assertions can verify that navigation is available, the hero does not cover the CTA, containers stay within bounds, and form controls remain reachable. Add action checks for opening menus, entering text, submitting forms, scrolling through sticky elements, and recovering after validation errors. These checks answer a more useful question than “which breakpoint failed?” They show which user action breaks.

ApproachWhat It Does WellWhere It Breaks Down
Screenshot comparisonsDetects fast visual regressionsFlags valid changes and misses interaction failures
Layout assertionsChecks structure, visibility, and relationshipsRequires deliberate test design
Action-based testsVerifies menus, forms, focus, and touch flowsNeeds maintenance as components change
Continuous runsCatches regressions on each commitCan create noise without risk-based scope
Human reviewInterprets context and intentCannot cover every release or device

A small WordPress team may also need a quick preview tool rather than a full CI setup. The WordPress Responsive Page Tester adds a Responsive button to the toolbar and displays the site in an overlay at different sizes. It can expose obvious visual issues before formal QA, but it does not prove that touch, focus, or performance behavior works.

AI visual checkers can help sort likely layout changes, yet they may miss foldable hinge states, hover-to-touch transitions, focus order, and slow-device behavior (QWE tutorial). Treat their output as a triage signal, not a pass/fail gate. Keep the automated suite narrow enough to maintain, then reserve real-device and human checks for the interactions analytics shows carry the most risk.

A Repeatable Workflow and Testing Checklist

The workflow that holds up in real teams is simple enough to repeat and strict enough to catch the expensive misses. Start with your highest-traffic templates, define the widths that matter, sweep them in DevTools, confirm on real devices, then automate the regressions that keep coming back. That sequence scales better than ad hoc testing because each layer does one job well.

Use this order

  • Baseline critical templates: Start with checkout, search, and article pages before lower-value screens.
  • Sweep widths in DevTools: Move from the smallest viewport upward, and drag slowly between breakpoints.
  • Check real devices: Confirm touch behavior, keyboard interaction, and rendering on actual phones and tablets.
  • Run automated comparisons: Keep responsive regressions from slipping back into later commits.
  • Throttle the network: Test slow-loading states, not just ideal desktop conditions.

The most common mistakes are still the easiest to avoid. Teams test only a few standard widths, rely on emulation exclusively, or skip performance under throttled networks. Those shortcuts save time early and create rework later.

Start with two or three highest-traffic templates this week. That's usually enough to surface the bugs that matter most, and it gives you a pattern you can expand without rebuilding the process.

The point of responsive design testing isn't to cover every possible device. It's to protect the user actions that fail most often under real conditions. If you keep the matrix tied to analytics and the workflow tied to actual page risk, the process stays manageable instead of turning into screen-size theater.


Read More Info publishes practical WordPress content, and this topic fits the kind of site work it already supports, from responsive layouts to core publishing workflows. If you're tightening your own QA process, visit Read More Info for more WordPress-focused guidance you can apply to a live site.

10 Feed Reader Chrome Options for Better Reading

Chrome Is Only the Starting Point

The most popular advice about choosing a feed reader Chrome extension is usually too narrow. Chrome doesn't include a built-in RSS reader, so feed reading in the browser can mean a toolbar extension, a browser-based cloud reader, or a self-hosted service opened in a tab. Chromium documents a workflow in which Chrome detects RSS or Atom feeds and lets you subscribe through the reader of your choice, but the actual reading experience depends on the tool you connect to it. (Chromium's feed-subscription documentation)

For Read More Info, add the main posts feed when you want new articles, or the comments feed when discussion updates matter. WordPress documents /comments/feed/ as the standard sitewide comments RSS 2.0 endpoint, with ?feed=comments-rss2 available as the non-pretty alternative. (WordPress feed documentation)

The right option depends on feed volume, alerts, full-text reading, automation, device sync, privacy, and maintenance tolerance. This comparison focuses on what each tool does inside Chrome, including toolbar capture, browser-only local reading, cloud workflows, and self-hosted control. The ten options group naturally into three workflows:

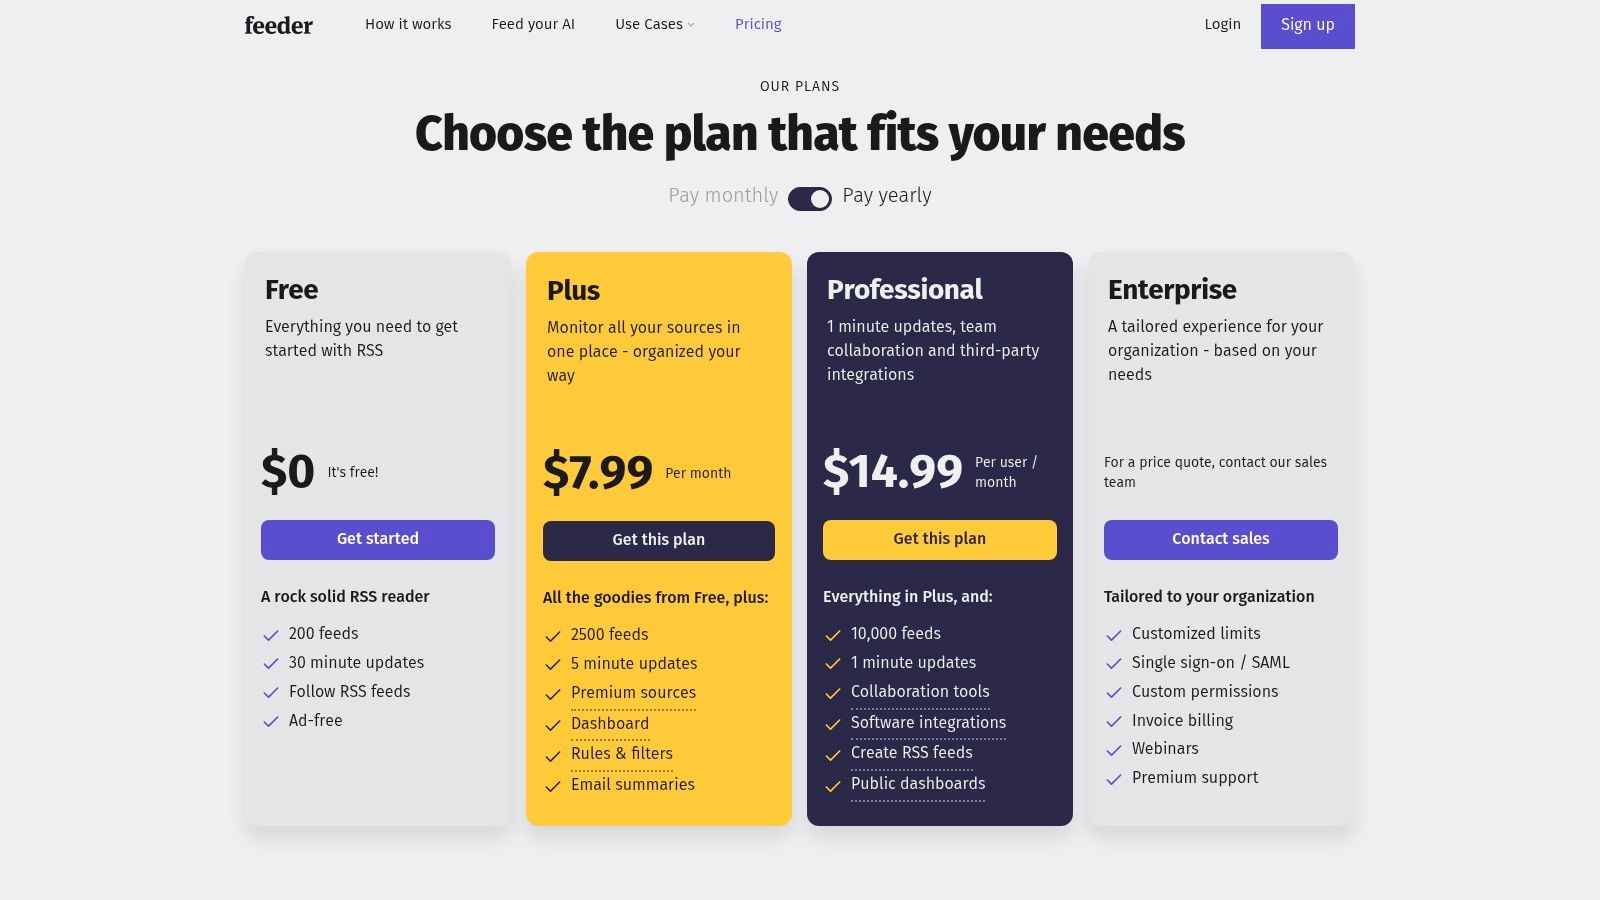
  • Extension-first: Feeder and Feedbro keep reading close to the Chrome toolbar or browser profile.
  • Cloud readers: Feedly, Inoreader, NewsBlur, Feedbin, BazQux Reader, The Old Reader, and Miniflux Hosted handle syncing through a web service.
  • Self-hosted readers: FreshRSS, Miniflux, and NewsBlur's open-source server option give you greater control over data and infrastructure.

Import a small OPML file or a few individual feeds first. Test refresh behavior, notifications, full-text extraction, mobile access, search, retention, and export before moving your entire library. For broader publishing and discovery guidance, see these technical SEO insights.

Table of Contents

1. Feedly

Feedly is the safest starting point for readers who want a polished cloud service rather than a Chrome extension that owns the whole experience. Open it in a Chrome tab, add feeds, and let the service keep reading state available across its web and mobile apps. It works for a personal reading queue, but its organization and monitoring features also support teams that need to follow subjects rather than just browse headlines.

The useful distinction is between basic aggregation and managed monitoring. Feedly supports OPML import and export, saved searches, filters, integrations, and AI Feeds. Its Feedly AI options can help users organize or monitor topics, while muting and deduplication are available on higher tiers. That makes it more suitable for a growing research library than a simple toolbar counter.

Feedly

Where Feedly fits

Feedly works best when you want cloud portability and discovery. You can open Chrome on a different computer, continue reading on a phone, and preserve a central collection instead of tying feeds to one browser profile. Its search and keyboard shortcuts make it practical for frequent reading, while higher plans extend it toward professional monitoring.

The trade-off is product complexity at the subscription boundary. Consumer pricing can be harder to interpret than enterprise offerings, and advanced filters, integrations, saved searches, and AI capabilities may require Pro+, an enterprise plan, or another paid level. Check the current plan page before designing a workflow around a feature.

For a WordPress publisher, the WordPress blog creation guide pairs naturally with Feedly testing. Subscribe to the posts feed first, then add the comments feed only if discussion monitoring belongs in your daily routine. Feedly is a strong general recommendation, but it isn't the best choice if your priority is local storage or a deliberately minimal interface.

2. Inoreader

Inoreader is built for people who don't want to process every item manually. Its web interface runs well in Chrome, but its core value comes from rules, filters, tags, dashboards, and automation. A large feed library becomes manageable when the reader can route items according to authors, keywords, topics, or other conditions instead of presenting one undifferentiated stream.

Its workflow is especially effective for monitoring and automation. Pro users get guaranteed hourly refresh, and the service offers full-text extraction for feeds that publish only summaries. AI summaries and intelligence features add another layer, with a choice of model or provider that gives advanced users more control than a fixed black-box feature.

The cost of control

Inoreader's flexibility creates its main weakness. New users can face a dense interface, and the number of available rules and dashboard choices can turn setup into a project. Translation and text-to-speech options also have daily caps on Pro, so users should test their intended workflow instead of assuming every automation runs without limits.

Practical rule: Use Inoreader when you can describe the rule you need. If you only want a calm chronological reading list, its control surface may be unnecessary.

The service suits editors, analysts, and marketers who need to separate alerts from reading. Add Read More Info's blog as a clean test feed, then create a second stream for comments if you need to identify discussion activity. Inoreader is a better fit than Feedly when filtering depth matters more than simplicity, but it demands more configuration discipline.

3. NewsBlur

NewsBlur takes a more personal approach to filtering. Instead of relying only on folders and unread counts, it lets readers train the service around authors, tags, titles, and full text. That makes it useful when a publication produces a mixture of subjects and you want the reader to learn which parts deserve priority.

Its River of News view provides a continuous reading mode, while text-view extraction can make partial feeds easier to consume. NewsBlur also offers web and native mobile apps, and its open-source server option gives technically confident users a path toward self-hosting without abandoning the same general product concept.

A practical middle ground

NewsBlur sits between a minimalist reader and a large monitoring platform. It has enough intelligence for selective reading, but its interface is more utilitarian than fashionable. That can be an advantage because the design keeps attention on the feed rather than on dashboard decoration.

The service is also appealing to individuals who want straightforward pricing and generous site limits. The least expensive tier omits some archive and AI capabilities, so the important question isn't whether NewsBlur has those features in principle. It's whether your reading habit depends on them.

For Chrome users, NewsBlur is a good choice when trainable filtering matters but enterprise-style automation feels excessive. It also offers a more credible self-hosting route than most cloud-first readers. Choose it when you want a reader that can grow with your habits, not when you need toolbar notifications as the center of the experience.

4. Feedbin

Feedbin is for readers who open Chrome to read, not to manage a complicated information system. Its interface emphasizes typography, speed, and a clean queue. Automatic full-text extraction can turn partial feeds into more comfortable reading experiences, while powerful search helps recover articles after the unread queue has disappeared.

The service also accepts newsletters through a built-in email address and supports podcasts and YouTube. That broader input model matters for people who want one reading environment without turning the browser into a collection of separate tabs and inbox searches.

Reading without dashboard fatigue

Feedbin's strongest trade-off is focus. It has app sync endpoints and useful actions, but it doesn't expose the same depth of rules and automation as Inoreader. That limitation is intentional enough to be valuable. Readers who want fewer decisions can get through a queue without constantly maintaining categories, filters, and smart streams.

There isn't a free tier, so the service needs to justify itself through reading quality rather than casual experimentation. In return, one plan includes most features without a long list of add-ons. That makes the purchase easier to understand, even though it removes the low-commitment entry point.

Feedbin suits a full-text reading habit across Chrome and mobile devices. It's less appropriate for people who need toolbar alerts, self-hosting, or complex topic surveillance. If your main objective is to read articles comfortably and search them later, its restraint is a feature.

5. BazQux Reader

BazQux Reader stands out when comments and threads are part of the material you read. It can display comments, discussions, and threads alongside normal feed entries, which makes it a particularly relevant option for testing a WordPress comments feed. Its mixed and magazine views provide different ways to scan a collection without forcing every source into one layout.

The reader also converts summary feeds into full-text views and includes smart stream filters. The interface is fast and lightweight, with typography that favors dense but readable browsing. Chrome is just the access point, so there's no extension installation to maintain and no toolbar dependency when you move between devices.

Best for discussion-heavy reading

BazQux is a paid-only service with a trial rather than a permanent free tier. It also isn't designed around posting content to social networks from inside the reader. Those limitations matter less if your workflow is private reading, research, and discussion tracking.

Its independent positioning brings a different trade-off from larger platforms. You get a focused product without ads or tracking, but you shouldn't expect the broad integration ecosystem or discovery features associated with bigger cloud services. The support model also feels more like an indie tool than a corporate platform.

Use BazQux when comments, full text, and speed matter more than social sharing. Add a sitewide feed for regular articles and a comments feed for discussion activity. It's one of the more distinctive choices in this list because it treats conversations as first-class feed content rather than an afterthought.

6. The Old Reader

The Old Reader is the choice for readers who miss the social feel of classic Google Reader. Its interface is familiar and minimal, with keyboard shortcuts that make ordinary scanning quick. The service also supports public sharing through blurblogs and community discovery, so it can expose you to feeds and recommendations beyond your private subscriptions.

The free plan supports up to 100 feeds, while Premium lifts limits and adds full-text search and longer retention. (The Old Reader) Those limits make the service easy to evaluate for casual monitoring, but heavier users need to understand when archive depth and search become paid features.

Social discovery versus automation

The Old Reader isn't trying to compete with Inoreader's rule engine or NewsBlur's trainable filtering. Its appeal is lower friction. You can add a familiar set of sites, read in Chrome, and optionally share items publicly without building a complex monitoring system.

Public pricing isn't always clearly listed before signup, with the premium price shown during the account process. That can make budgeting less transparent than services with a detailed plan page. Check the current terms before moving a large archive or relying on a premium retention feature.

Choose The Old Reader when social discovery and simple reading are more important than automation. It works well for a personal list of publications, but it won't be the first recommendation for technical SEO monitoring, complex editorial alerts, or a large rules-driven library.

7. Feeder

Feeder is strongest when reading starts in Chrome's toolbar rather than in a dedicated dashboard. Its extension lets you add a feed from the page you are viewing and receive browser notifications as new items arrive. That suits casual monitoring and alert-led workflows, especially if opening a cloud reader throughout the day is unnecessary.

A web reader and mobile apps extend the service beyond the browser, while OPML import and export provide an exit route if your setup changes. Paid tiers can create feeds for sites without RSS through AI Feeds. Plus or Pro may matter for faster polling and stronger search as subscriptions grow, so compare plan costs with the value of timely alerts and archive access before committing.

Alerts first, reading second

Feeder reduces capture friction: discover a site, subscribe from Chrome, and continue browsing. Test Read More Info's main RSS feed alongside its comments feed to see whether article updates or discussion alerts better match your routine.

The trade-off is attention and depth. Notifications support casual monitoring, but full-text reading and long-term research may require another workflow. Search and automation are less central than in a cloud reader built around rules. Privacy depends on accepting a hosted service, while technical maintenance stays low because Feeder handles the service side. Social discovery is also secondary, since its value lies in capture and alerts rather than community features.

Choose Feeder for alerts, quick subscription, and browser proximity. It fits readers who check updates promptly and want low setup effort. Choose another tool if advanced automation, extensive research, social discovery, or self-hosted control matters more than toolbar access.

8. Feedbro

Feedbro keeps the entire reading workflow inside Chrome. It runs as a local-first RSS, Atom, and RDF extension without requiring an external account, which makes it attractive to readers who want advanced rules while keeping feed data in the browser profile.

Multiple viewing modes, keyword highlights, filters, and full-text extraction give it more depth than a basic notification extension. It can also handle sources associated with social platforms, YouTube, and Reddit, and it supports offline operation through the Chrome profile. OPML import and export provide a practical escape route if you later change tools.

Local control has a portability cost

Feedbro's privacy and subscription model are straightforward because there's no external service account required for ordinary use. The downside is device continuity. Syncing depends on Chrome profile sync rather than a dedicated reader cloud, so the experience is less independent of Chrome than Feedly, Feedbin, or Inoreader.

A very large library may also put pressure on the browser because the extension handles storage and processing locally. That isn't a reason to reject it, but it is a reason to start with a controlled set of feeds and observe performance.

Feedbro is a strong option for users who value local reading, offline access, and no subscription. A site owner can test both article updates and conversation tracking with these WordPress blog layout examples, then decide whether local filtering is enough. It won't offer the same effortless multi-device workflow as a cloud reader, but it gives Chrome users unusually direct control.

9. FreshRSS

FreshRSS turns Chrome into a window onto infrastructure you control. It's an open-source web reader that can be self-hosted or placed with a managed host, so the browser experience resembles any other web application while the data and update cadence remain under your administration.

The software supports multiple viewing modes, keyboard shortcuts, themes, multi-user access, and extensive documentation. It's lightweight enough to run on low-resource servers, which makes it practical for a solo creator or small team that wants ownership without operating a large application stack.

Privacy means accepting maintenance

FreshRSS gives you control over storage, upgrades, backups, and access policies. That's meaningful for readers who don't want a third party to hold their subscriptions and reading history. It also introduces responsibilities that cloud services absorb for you, including installation, security updates, server availability, and recovery planning.

Full-text extraction for partial feeds may require plugins or external tools. Before migrating, test the feeds you care about rather than assuming every article will appear in full. A self-hosted reader can be private and reliable, but only when someone actively maintains it.

FreshRSS is the best fit when data ownership and self-hosting outweigh convenience. It works particularly well for editors, small businesses, and technical users who already maintain a server. Choose a managed host if you want the privacy model without handling every operational task yourself.

10. Miniflux

Miniflux strips RSS reading down to the parts that matter. Its interface is fast, keyboard-centric, and intentionally sparse, with categories, tags, and star or save actions rather than a crowded collection of dashboards. You can access the hosted service from Chrome or run the open-source application on your own server.

The hosted option uses the same open-source codebase as the self-hosted version. That makes the transition between convenience and control more predictable than a service that changes its hosted product substantially. The maintainer also discloses data location, which gives privacy-conscious users a concrete detail to evaluate.

Minimalism is a deliberate boundary

Miniflux doesn't try to provide every social, AI, or automation feature. That keeps it stable and quick, but it also means users who want rich discovery, complex rules, or extensive integrations may find it too limited. Its pragmatic retention policy reinforces the idea that a feed reader should help you process information, not become a permanent archive of everything.

Hosted accounts require manual annual renewal rather than automatic renewal. That is easy to overlook, so add it to your operational routine if you depend on the hosted service for daily reading.

Miniflux suits focused readers who want speed, privacy, and low cognitive overhead. Self-host it when you want control, or use the hosted version when you want the same general experience without server administration. It isn't the universal answer, but its limitations are clear and often refreshing.

Top 10 Chrome Feed Readers Comparison

Reader✨ Key features★ UX / Quality💰 Price & value👥 Best for🏆 Unique selling point
FeedlyWeb + mobile; AI feeds; dedupe; saved searches★★★★☆ (4/5)Free + Pro/Pro+; 💰 scales from casual→teams👥 Casual readers → teams/monitoring🏆 Mature ecosystem & AI options
InoreaderRules, filters, dashboards; AI summaries★★★★☆ (4/5)Free + Pro; clear limits; 💰 strong for heavy use👥 Power users & researchers🏆 Deep automation & fast refresh
NewsBlurTrainable filters; text view; optional self-host★★★★ (4/5)Free + Premium; 💰 good individual value👥 Individuals who want control & training🏆 Trainable prioritization & self-host
FeedbinFull-text extraction; newsletter ingestion; podcasts★★★★ (4/5)Paid-only (single plan); 💰 simple predictable pricing👥 Privacy-minded, distraction-free readers🏆 Excellent typography & newsletter ingest
BazQux ReaderComments/threads; full-text; lightweight UI★★★★ (4/5)Paid (trial available); 💰 paid-for speed👥 Readers who value speed & threaded comments🏆 Fast, clean UI with thread reading
The Old ReaderSimple UI; sharing (blurblog); keyboard shortcuts★★★ (3/5)Free (≤100 feeds) + Premium; 💰 casual-friendly👥 Casual readers who miss Google Reader🏆 Community sharing & familiar UX
FeederChrome extension + web/mobile; notifications; AI feeds★★★★ (4/5)Free + Plus/Pro; 💰 great for extension-first workflow👥 Chrome users wanting real-time alerts🏆 Toolbar extension with quick notifications
FeedbroLocal-first Chrome extension; rules; offline mode★★★★ (4/5)Free extension; 💰 no subscription needed👥 Users wanting local/offline control🏆 Runs entirely in browser; offline operation
FreshRSSSelf-hostable; lightweight; multi-user & theming★★★★ (4/5)Free OSS (hosting cost); 💰 low-cost self-host option👥 Self-hosters & privacy-focused users🏆 Full data control + light resource use
MinifluxMinimal, keyboard-centric UI; hosted & self-host★★★★ (4/5)Free OSS; hosted paid with manual renewal; 💰 minimalist pricing👥 Minimalists seeking speed & simplicity🏆 Extremely fast, privacy-first minimal reader

Choose the Workflow You Will Maintain

There isn't one universal winner because the important decision is where reading begins and who maintains the system. If Chrome toolbar access and immediate alerts are central, start with Feeder. It makes feed discovery and notifications feel native to the browser. Choose Feedbro when you want that browser-first relationship without an external account and you're comfortable tying storage and device continuity to Chrome.

For cloud-based discovery and monitoring, Feedly and Inoreader are the strongest starting points. Feedly offers the more approachable path from casual reading to professional monitoring, while Inoreader rewards users who will invest time in rules, filters, dashboards, and automation. NewsBlur belongs in the same general cloud category, but its trainable filtering and optional self-hosting make it a better match for readers who want a more personal system.

Focused readers should compare Feedbin and Miniflux. Feedbin is the cleaner choice for full-text reading, newsletters, podcasts, and a polished experience across devices. Miniflux is better when minimalism, keyboard control, and privacy matter more than discovery features. BazQux Reader deserves special consideration when comments and threads are important content rather than incidental metadata. The Old Reader remains the practical choice for a familiar interface with optional community discovery.

Self-hosting changes the maintenance equation. FreshRSS gives you a broad, documented platform with multi-user support and themes. Miniflux provides a more deliberately constrained experience, while NewsBlur offers an open-source server path for users who want its filtering model. Self-hosting doesn't remove operational work. It moves responsibility for updates, backups, access, and uptime to you or your managed host.

Start with a small test set instead of importing everything at once. Add Read More Info's posts endpoint, /feed/, and its comments endpoint, /comments/feed/, when discussion monitoring is relevant. Then check notification timing, full-text behavior, search quality, retention, mobile access, and backup or OPML export. A reader that looks excellent with a few feeds may become frustrating once filters, archive expectations, and device switching enter the workflow.

Chrome's extension ecosystem has become a substantial alternative to a native RSS feature. One Chrome Web Store RSS reader listing reports 500,000 users and 7,400 ratings, illustrating the scale of the browser workaround. (Chromium's feed-subscription background) Another listing reports availability in 42 languages, compatibility with Chrome 109 and later, and a 4.3-star rating from 7.4K ratings, with an update date of August 31, 2026 visible on the listing. (Chrome Web Store RSS reader listing) Those details indicate a maintained category, but they don't eliminate the need to test privacy, portability, and plan limits for yourself.

Review each service's current pricing and feature limits before committing. Plans, polling rules, AI capabilities, retention, and renewal terms can change, so the best reader is the one whose ongoing maintenance matches the way you read.


Read More Info publishes WordPress posts and updates through a clean main RSS feed, while its comments feed lets you follow new discussion activity without checking every page manually. Visit Read More Info to test both endpoints in the Chrome reader that fits your workflow and discover more practical information for everyday reading.

What Is Feed Reader

You open your browser on Monday morning and find a familiar mess waiting for you. News sites, blogs, podcasts, research pages, and industry publications are scattered across dozens of tabs. You refresh the same pages, skim headlines between tasks, close a few tabs, then reopen them because you're not sure whether you missed something important.

The problem isn't a lack of information. It's the repeated effort of checking every source separately. A feed reader gives those updates one place to go, so you can follow new content without manually revisiting every website.

Table of Contents

The Moment You Realize You Have Too Many Tabs Open

By mid-morning, your browser feels like an unfinished to-do list. One tab contains a technology blog you meant to read last week. Another holds a newspaper section you check several times a day. A third is a podcast page, and somewhere behind them is a research site you don't want to lose.

You scroll through ads, dismiss cookie notices, and refresh pages that may not have changed. Even after all that work, you still can't tell whether you've seen every new article. The mental cost is easy to underestimate. Each tab asks you to remember why it matters, when you last checked it, and whether the latest item deserves your attention.

A woman drinking coffee while working on her laptop in a bright and cozy home office.

Most of those websites probably publish an RSS feed, a small, machine-readable stream of updates. You don't usually need to understand the file itself. You subscribe to the feed in an app, and the app gathers new items into one reading queue. Instead of visiting ten sites to look for changes, you open one place and scan what has arrived.

That same principle can help when you're evaluating newer ways to reduce repetitive browser work. For a broader look at automated browsing workflows, explore browser use AI tools 2026. A feed reader isn't a browser agent, though. It follows publisher feeds and organizes their updates, leaving you in control of what you read.

A simple WordPress publication such as this example site can provide a useful starting point. Add its feed to a reader, add a few other sources you trust, and the scattered tabs become a single, chronological stream.

The important shift is psychological as much as technical. You stop asking, “Which sites should I check?” and start asking, “What new items have arrived?”

A Feed Reader in Plain English

A feed reader is software that collects updates from websites and displays them in one ordered stream. It may be a web app, desktop program, browser extension, or mobile app. You might also hear RSS reader, news aggregator, or feed aggregator. In everyday use, these terms describe tools that subscribe to feeds and present their contents for reading.

The simplest analogy is a set of mailboxes. Each website places new notices in its own mailbox. Your feed reader acts like a homeowner who checks all those mailboxes on a repeating schedule, brings the new notices inside, and places them in one inbox.

The website isn't sending a personal email every time it publishes. It updates a public feed, and your reader checks that feed. The reader then shows information such as:

  • Title: The name of the new article, episode, or update.
  • Link: The address that takes you to the original item.
  • Summary: A short description, when the publisher provides one.
  • Date: A signal that helps the reader order entries and identify changes.

RSS itself is an XML-based format for syndicating web content. The format is the mailbox, not the person collecting the mail. The app is the reader, while the feed is the structured document that carries the publisher's updates. RSS 2.0 remains the most widely deployed version, according to the RSS 2.0 profile.

A diagram illustrating how a feed reader works by collecting content from websites into one stream.

A useful feed reader definition is therefore: an application that checks subscribed content feeds, identifies new entries, and presents them in a readable list. When someone searches for “what is feed reader,” “what is a feed reader app,” or “RSS reader meaning,” they're usually trying to understand this relationship between the website, the feed, and the application.

You don't need to open an XML file to use one. The reader translates the structured data into headlines, dates, excerpts, folders, and reading controls. You can mark an item read, save it, open the original page, or remove a subscription.

The practical model: Websites publish. Feeds carry the updates. Feed readers collect and organize them.

That model is enough to begin. The technical details explain why the system can follow many sources without requiring you to keep checking each site.

How a Feed Reader Actually Works Behind the Scenes

A feed reader repeats a small cycle. It contacts a feed, receives structured information, compares that information with what it already knows, and displays anything new. The process sounds technical, but it resembles checking a shared noticeboard and remembering which notices you've already read.

First the reader requests the feed

The reader stores the address of every feed you subscribe to. At intervals, it sends a request to each address. Many readers use a schedule that may range from 15 to 60 minutes, as represented in the process diagram below, while other systems use different defaults or allow manual refreshes.

A diagram explaining the three steps of how an RSS feed reader works behind the scenes.

The website's server returns an XML document. In a typical RSS 2.0 structure, one rss element contains a channel, and that channel contains item elements. The RSS implementation overview describes this basic arrangement.

Think of channel as the information about the publication itself. It may include the site's name, description, and feed address. Each item is one entry, such as a blog post or podcast episode.

Then the reader parses the XML

The reader looks inside each item for familiar fields:

  • title gives the entry its headline.
  • link points to the original web page.
  • pubDate helps establish when the item was published.
  • description or a similar field may provide an excerpt.
  • guid gives the item a persistent identifier that helps distinguish it from other entries.

XML uses tags to label information for software. A human can read the labels, but the reader doesn't need visual design, advertising scripts, or page layout to understand that one item has a title and another has a link.

The reader compares the identifiers and metadata with its local record of previously seen entries. If an item has a new identifier, or the publisher has changed relevant information, the reader can place it in the stream or mark it as updated.

Finally it displays the change

New items generally appear near the top of a reverse-chronological list. You can scan several sources together, open only the entries that interest you, and leave the rest marked as read. The reader may also store your folders, saved items, and read status, depending on the product.

This is why a feed reader can monitor many sites with relatively little effort. The publisher maintains the feed, the reader performs the checking, and you review the resulting list. Podcast publishers use the same subscription model for audio distribution, and a specialized secure audio delivery guide can help explain how private podcast feeds apply the same underlying idea.

A reader doesn't necessarily download a complete web page every time. Conditional requests let the client ask whether the feed has changed before transferring the full document. Caching can reduce repeated work for both the server and the device, while WebSub can support faster push-style notifications where the publisher and reader support it. The RSS best-practice guidance discusses compatibility, content types, full-content feeds, conditional retrieval, and WebSub.

A Short History of Feed Readers and Why They Came Back

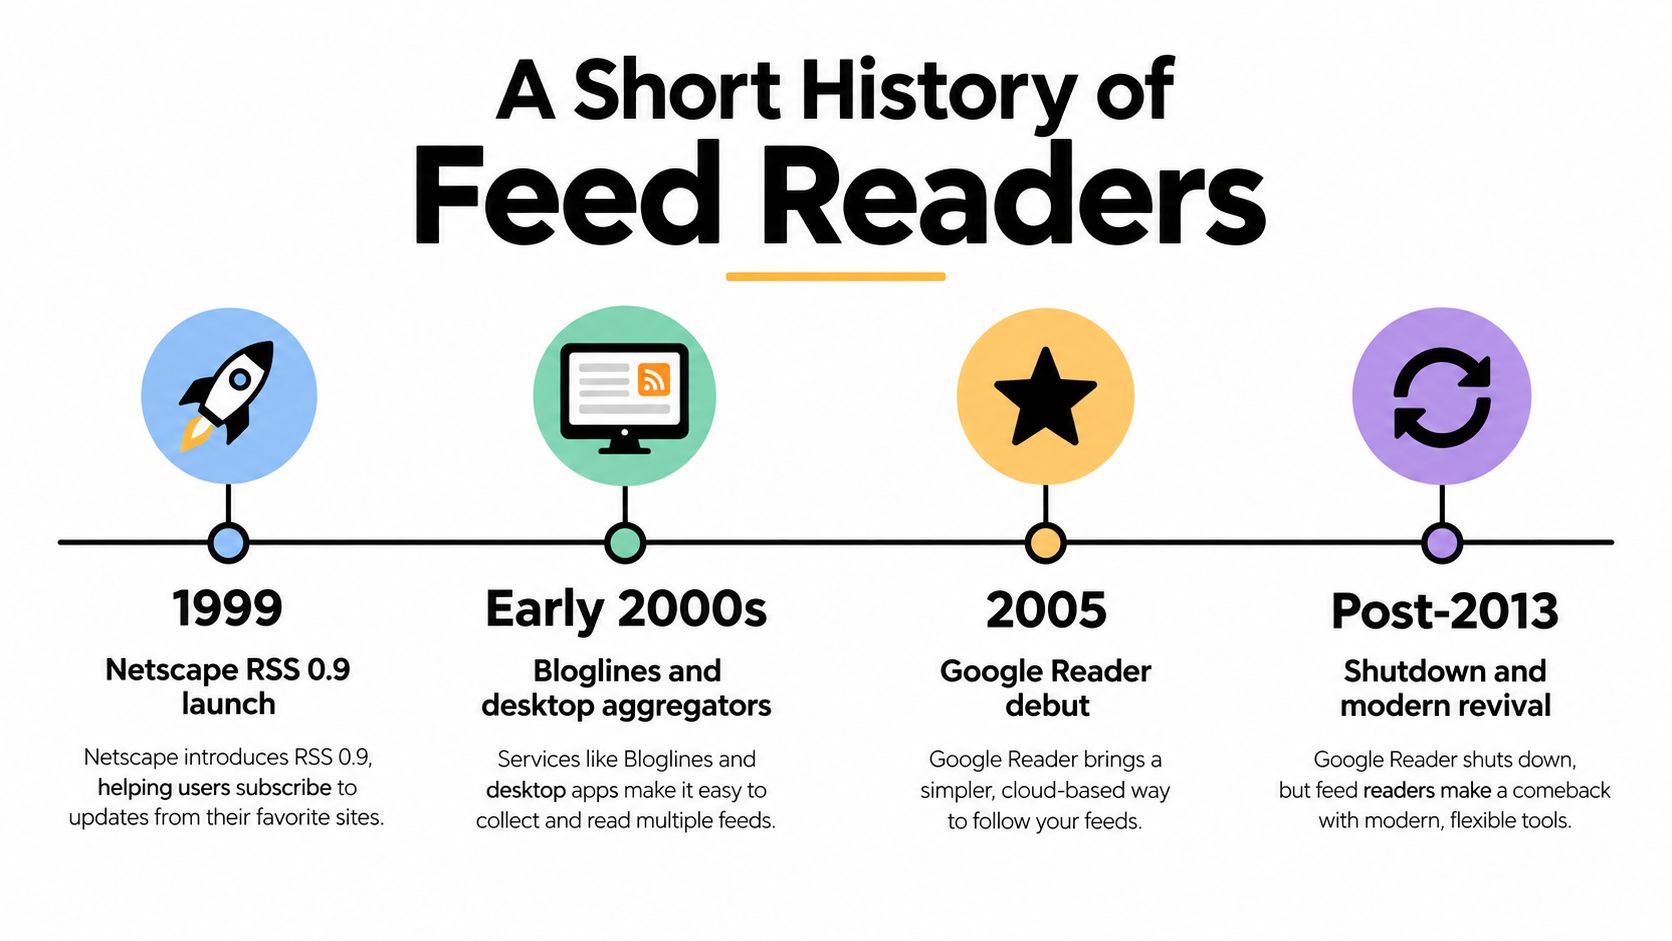
RSS began as a way to make changing web content easier for software to distribute and collect. Netscape introduced the underlying standard in 1999, and later milestones included RSS 1.0 in December 2000 and RSS 2.0 in September 2002. Each stage made it easier for publishers and applications to exchange updates through a common structure, as documented in the history of RSS and feed readers.

The format gained credibility when major publishers adopted it. In 2002, The New York Times began offering RSS feeds, helping move the technology beyond a niche developer audience. By the middle of the 2000s, readers could use feeds to collect posts from blogs and updates from news sites instead of visiting every publication independently.

A timeline graphic illustrating the evolution of feed readers from 1999 to post-2013 developments.

Browser support helped make the concept more visible. In 2005, Internet Explorer, Firefox, and Safari began supporting feeds directly. Google Reader launched on October 7, 2005, making inbox-style feed reading familiar across devices. For many readers, the attraction was straightforward: subscribe once, then return to one list instead of maintaining a personal map of changing websites.

The turning point came when Google shut Reader down on July 1, 2013. The closure showed how dependent many users had become on a single service, but it also fragmented the market. People moved to different readers, followed publishers through social platforms, or relied on newsletters and dedicated podcast applications.

The technology itself didn't disappear. RSS remained embedded in publishing systems, podcast distribution, and independent web communities. A technical survey of RSS feeds found that more than 98% of the 97,720 feeds examined were in RSS format, illustrating how widely the format was used in practice. The same Cornell RSS survey also discusses the reader behavior and feed characteristics that support this model.

That persistence explains the renewed interest in feed readers. People who want a chronological, cross-site reading space can use an open standard instead of depending entirely on a platform's ranking system. The experience feels less like chasing updates across separate services and more like maintaining a personal publication shelf.

Feed Readers Versus Newsletters and Algorithmic Feeds

A newsletter arrives in your email inbox. A social feed appears inside a platform. An AI-curated timeline selects and orders information for you. A feed reader collects the sources you chose and usually presents their entries in a reverse-chronological stream.

The difference is control. A newsletter publisher controls the delivery schedule and email format. A social platform controls which posts receive visibility. An AI summary tool controls what it considers relevant enough to show. With RSS, you choose the publication, add its feed, and decide what to open.

MethodWho Controls OrderTypical PrivacySubscription Effort
Feed readerYou and the reader's sorting settingsUsually limited to the reader and subscribed feedsCopy or discover a feed, then add it
NewsletterPublisher and email serviceEmail address and email interaction data may be involvedEnter an address and manage email delivery
Social feedPlatform ranking systemPlatform account and behavior data are involvedCreate or use an account, then follow sources
AI-curated timelineAI service and its configurationDepends on the service, account, and connected dataConnect sources and adjust preferences

Newsletters can be useful when a writer intentionally produces a digest. They also compete with ordinary email, promotional folders, spam filters, and crowded inboxes. A feed reader separates publication updates from personal correspondence, which makes scanning easier for readers who want a dedicated information space.

Social feeds offer discovery and conversation, but they don't promise that you'll see every post from every account you follow. Ranking systems may place popular, recent, sponsored, or personalized content ahead of quieter updates. AI-curated timelines can reduce reading effort, yet summaries may hide the original context or make it harder to tell what the source published.

RSS has trade-offs. Setup takes a little more initiative, and some publishers don't expose a feed or provide only short excerpts. You may also need to open the original page for the full article. Still, the subscription remains easy to remove, and the reading list doesn't depend on a platform deciding which update deserves your attention.

A feed reader is best for deliberate follow-through, not endless discovery. Choose the sources first, then let the reader handle collection.

Where to Find Feeds and How to Subscribe in Real Life

Finding a feed is usually easier once you know what signals to look for. Start on a site you already visit, such as a blog, newspaper section, research publication, or podcast page.

Use the visible clues first

Look for an orange RSS symbol, or text such as RSS, XML, Subscribe, Feed, or Alerts. The link may appear in the site's footer, navigation menu, sidebar, or browser interface. Select it and see whether your browser displays a structured page containing repeated titles and links. That page is often the feed itself.

Some browsers and extensions can detect a feed through the page's auto-discovery information. If you inspect the page source, look for a link element identifying an RSS or Atom document. You don't need to edit the source. You're only confirming that the publisher has exposed a feed address.

A quick test is to paste the suspected address into a feed reader. If the reader shows a publication name and a list of entries, you've found a usable feed. A standard WordPress site often uses /feed/ for its main posts feed, while /comments/feed/ can provide a separate stream for site-wide discussion. WordPress documentation describes both the site-wide comments endpoint and individual post comment feeds in its guide to WordPress feeds.

Add the address to a reader

Copy the feed address, open Feedly, Inoreader, NetNewsWire, or another reader, and choose its add-subscription option. Paste the address, confirm the matching publication, and place it in a folder such as News, Industry, Research, or Podcasts.

If the site has categories, check whether each category exposes its own feed. A category feed is useful when you want one topic rather than every post from the publication. WordPress publishers can also expose individual comment feeds, which helps readers follow discussion without repeatedly opening each article.

You can use this WordPress blog example to practice the discovery process. Look for the site's feed link or test the standard feed path in your reader, then confirm that the publication title and recent posts appear.

Troubleshoot the common failures

A 404 response usually means the address is wrong, the publisher removed the feed, or the site uses a different endpoint. Try searching the site for RSS or Subscribe, checking its footer, or adding the site's main address directly inside the reader.

A feed may show headlines and short summaries rather than full articles. That's a publisher choice, not necessarily a reader error. Open the original link for the complete text, and check whether the reader offers a setting to display the source page.

Use the HTTPS version when the publisher provides one. If a reader rejects an insecure or redirected address, find the secure feed link and add that instead.

Keep this checklist nearby:

  • Choose a source: Start with a site you already trust.
  • Find its signal: Search for RSS, Feed, Subscribe, or Alerts.
  • Test the address: Paste it into a reader and check the entries.
  • Sort the subscription: Put it in a folder you'll recognize.
  • Check the result: Open one item and confirm that the link reaches the original page.

Choosing a Feed Reader and Getting Started This Week

The best reader is the one that fits the way you already work. A web-based reader such as Feedly is convenient if you move between computers and phones. A desktop application such as NetNewsWire suits readers who prefer keyboard shortcuts, a focused reading window, and local app behavior. A self-hosted option such as FreshRSS appeals to people who want more control over where their subscriptions and reading data reside.

Reader StyleBest ForTypical CostLearning Curve
Web-based readerBeginners and people using several devicesFree tiers or paid plans may be availableLow
Desktop appKeyboard-focused reading on a computerOften free, with features depending on the appLow to moderate
Self-hosted readerTechnical users who want data ownershipSoftware may be available at no charge, but hosting requires setupModerate to high

Don't choose based only on the longest feature list. Check whether the reader syncs read status between your devices, whether it has a mobile app, how it handles full-text feeds, and whether its folders match your habits. A reader that opens quickly and makes subscriptions easy will serve you better than a powerful tool you avoid.

A practical starting plan can fit into one week:

  1. Today: Pick one reader and subscribe to five sources you genuinely want to follow.
  2. By day three: Remove feeds that publish too often, no longer interest you, or add noise.
  3. Later in the week: Create a small folder structure, perhaps News, Work, Ideas, and Audio.
  4. At the end of the week: Save a few useful articles and decide on a regular reading time.

You can also use a guide to creating a WordPress blog if you're considering publishing a feed of your own. The same standard that helps you follow other sites can make your future posts easier for readers to discover.

The goal isn't to collect every possible subscription. It's to build a calm, useful stream that replaces repetitive checking with a habit you can maintain.


Read More Info offers WordPress-based articles, site updates, and RSS feeds that make it easy to follow new posts in the reader you choose. Visit Read More Info to explore its content and use the site as a practical first subscription while you build your personal feed collection.

10 RSS Feed Reader Best Picks for Every Platform

The most popular advice about the rss feed reader best is usually wrong because it assumes every reader wants the same thing. A solo researcher handling a large queue needs different controls from someone who follows a few blogs on an iPhone. Your real decision depends on source volume, triage habits, platform, privacy expectations, full-text reading, automation, and whether you're willing to maintain a server.

RSS works because the format is open and predictable. RSS 2.0 is an XML-based syndication format built around a standard channel and item structure, which lets one reader collect updates from many websites through a common interface. The RSS 2.0 specification documents that structure. For a practical test, subscribe to Read More Info's main RSS feed and its separate comments RSS feed. WordPress documents that comments can be syndicated independently from site content through a comments feed, which makes this a useful test of both publishing and discussion monitoring. WordPress feed documentation explains the distinction.

This roundup compares how ten readers behave in real workflows, including their limitations, platform fit, and implementation effort. It moves from managed, automation-heavy services to focused native apps, browser tools, and self-hosted options. The aim isn't to repeat promotional feature lists. It's to help you build a daily reading system you'll actually keep using.

Table of Contents

1. Feedly

Feedly is the sensible starting point for people who want a managed cloud reader with broad discovery and a mature ecosystem. It handles folders, tags, saved searches, newsletter capture, and integrations with automation services such as Zapier and IFTTT. The interface is approachable enough for a first subscription, but it also gives researchers and teams room to build more deliberate monitoring workflows.

The Newsletter-to-RSS inbox is particularly useful when a publisher offers email updates but no public feed. You subscribe using a unique Feedly email address, then keep those messages beside ordinary RSS sources. That prevents newsletters from becoming a separate reading queue. Feedly can also support workflows around creating a WordPress blog, where the site's feed becomes the reliable distribution layer after publication.

Feedly

Best for managed discovery

Feedly's strongest advantage is the combination of easy onboarding and ecosystem depth. It works well when you want one service to discover sources, read them, save items, and pass selected stories into other applications. Its apps and integrations also make it a practical backend for third-party reader clients.

The compromise is plan complexity. AI-assisted filtering, summarization, market monitoring, and threat intelligence workflows are concentrated in higher tiers, so the most advanced experience isn't the basic reader experience. Individual and business plans also serve different needs, which can make the pricing path harder to understand than the clean interface suggests.

Practical rule: Choose Feedly when reducing setup friction matters more than maximizing local control.

It's a strong fit for marketers, analysts, and teams that need discovery plus automation. It's less attractive if you want a permanently free, minimalist reader or if you prefer to keep reading and data management outside a large hosted ecosystem.

2. Inoreader

Inoreader suits power users who want the reader to perform triage before they open an article. Its core strength is automation through rules, filters, tags, and notes. Instead of scanning every headline manually, you can route items based on words, sources, or other conditions and create a more purposeful stream.

That distinction matters once a subscription list becomes noisy. Inoreader can monitor standard RSS feeds alongside YouTube channels, podcasts, newsletters, social sources, and web feeds for sites that don't expose a native RSS endpoint. Its mobile apps also support rules and filters, so the automation isn't limited to a desktop session.

Best for high-volume monitoring

The service is at its best when you already know what you want to capture. A researcher can separate alerts from background reading. A content team can collect mentions, competitor updates, and industry sources into different workflows. A small business owner can use tags and notes to turn the reader into a lightweight research inbox rather than a simple headline list.

The trade-off is that advanced controls sit behind paid tiers, and plan details can vary by locale. That means you should test the exact rule, web-feed, and newsletter functions you need before importing a large source list. A feature can exist in the product while remaining unavailable to the plan you selected.

Inoreader also rewards maintenance. Rules need clear names, overlapping filters need occasional review, and automatic tagging can create clutter if every possible condition becomes a separate workflow. It isn't the best choice for someone who only wants a quiet chronological list.

Use it when the question isn't merely “What was published?” but “Which new items deserve my attention, and where should they go?”

3. Feedbin

Feedbin takes a quieter approach. It's a paid, ad-free reader built around chronological reading, full-text extraction, reliable synchronization, and native-app support. That focus makes it especially appealing to readers who don't want a discovery platform crowded with recommendations or business-oriented dashboards.

Its full-text extraction can turn a truncated feed into a more complete reading experience. Newsletter capture gives email-based publications a place in the same queue, while podcast and YouTube channel support extends the system beyond conventional articles. Powerful search and automatic actions help you retrieve and sort material without turning every reading session into an exercise in configuration.

Best for focused paid reading

Feedbin works particularly well with NetNewsWire and Reeder, giving Apple users a capable backend while preserving a clean native reading experience. It also fits people who want full-text access without manually opening every source website. The reading model is straightforward: subscribe, scan in order, save what matters, and return to search when you need it.

The major limitation is just as clear. There's no free tier, so Feedbin is a poor fit for readers who are still deciding whether RSS belongs in their routine. The paid-only model is easier to understand than a crowded tier structure, but it still creates an upfront commitment.

A good paid reader should remove recurring friction, not merely add more controls.

Feedbin is worth considering when ads, algorithmic ranking, and inconsistent feed content interfere with reading. It's less suitable if discovery, social monitoring, or broad automation is your primary requirement. For a small, deliberate source list and a full-text reading habit, its restraint is the feature.

4. NewsBlur

NewsBlur combines a hosted RSS service with an open-source path for users who want greater control. Its distinctive feature is trainable filtering. You can teach the reader which authors, tags, and words matter, allowing the system to separate interesting material from recurring noise.

The “River of News” folder view is designed for reading multiple feeds as one continuous stream. Text view extraction and full-text search make it more useful when publishers provide incomplete feeds, although some of those capabilities require paid access. Native iOS and Android apps keep the service practical for people who move between devices.

Best for a trainable workflow

NewsBlur is a good middle ground between a simple hosted reader and a fully self-managed installation. You can begin with the hosted service, learn how your reading habits work, and consider self-hosting through Docker if data ownership becomes more important. That path is valuable because it avoids forcing a server decision before you know whether you'll maintain it.

The self-hosting option also changes the responsibility boundary. You control the deployment and data, but you become responsible for updates, backups, availability, and troubleshooting. Hosted plans remove much of that work, while higher plans may be needed for faster fetching, archive depth, or full-text search.

The service's pricing is comparatively transparent, and its Premium option is generous for readers who want more than a basic account. Still, NewsBlur isn't frictionless for everyone. Trainable filters need attention, and a poorly designed training habit can hide useful articles along with irrelevant ones.

Choose it if you want the reader to learn your preferences and you value a credible route toward self-hosting. Choose a simpler service if you'd rather apply no rules at all.

5. The Old Reader

The Old Reader is for people who miss a familiar, uncluttered web reading experience. Its Google Reader-style interface puts the emphasis on subscriptions, unread items, folders, and straightforward scanning. The design feels less like a research platform and more like a dependable reading shelf.

That simplicity is useful for beginners. You can add a few sources, open the unread queue, and read in a predictable order without learning a large automation system. Social sharing and community features, including the blurblog, add a layer of interaction for readers who want to share or follow public activity around feeds.

Best for a familiar browser routine

The Old Reader makes sense when your primary device is a browser and your ideal reader is visually restrained. It's also a useful option for people who want a free entry point before paying for features such as full-text search and faster refresh.

The limitation is that the free tier has smaller feed caps than paid plans. Premium pricing and fuller plan details are presented during checkout rather than clearly exposed in a public comparison, so verify the current limits before committing to a large import. That lack of pricing visibility can make long-term planning harder, especially for teams or heavy users.

Its social features are a benefit only if you'll use them. Readers looking for private, solitary reading may find the blurblog model unnecessary. Conversely, someone seeking advanced rules, web monitoring, or newsletter automation will likely outgrow the service.

The Old Reader is best when the product's restraint matches your routine. It won't win on the longest feature list, and that's precisely why it remains appealing to readers who want fewer decisions between opening the app and reading an article.

6. BazQux Reader

BazQux Reader is a focused paid reader for people who care about speed, privacy, and getting the article into the reading pane. Its interface is intentionally minimalist, and its full-text conversion is one of the more practical reasons to choose it. Truncated feeds are less disruptive when the service can retrieve a fuller version for in-reader reading.

BazQux also brings article comments into the reader. That makes it useful for publications where discussion is part of the value, not merely an afterthought. It can monitor some social pages, including Facebook, Telegram, and VK, which gives it more range than a strict RSS-only tool without turning it into a general-purpose social dashboard.

Best for low-distraction full text

The interface feels fast because it avoids unnecessary layers. You can work through a queue, open the converted article, and keep your attention inside one reading environment. The no-ads design also supports a more private, concentrated workflow than many broad content platforms.

The drawbacks are concrete. There are no native mobile apps, so mobile use depends on the web app and the quality of your browser experience. BazQux is also paid-only beyond its trial, which rules it out for readers who need a permanent free option.

That trial is important. Use it to test the sources you read, because full-text extraction depends on how each publisher structures its feed and page. Also test comments if discussion monitoring is central to your work. A reader can advertise full-text support while still behaving differently across sites.

BazQux is a strong pick for someone who wants a fast, private reading surface and doesn't need a native app. It's not the right choice if mobile application polish or a free long-term plan outranks full-text convenience.

7. NetNewsWire

NetNewsWire is the clearest choice for an Apple-centered workflow. It's a free, open-source native reader for macOS and iOS with a modern interface, strong performance, and iCloud sync. The app feels like a native utility rather than a web service placed inside an application shell.

You can use iCloud for synchronization or connect NetNewsWire to external backends such as Feedbin, Feedly, and Inoreader. That flexibility matters because it separates the reading client from the service that fetches and stores feeds. You can choose a hosted backend for convenience or a different arrangement when control and portability matter more.

Best for Apple ergonomics

The main benefit is not an unusual feature. It's speed, keyboard-friendly navigation, and platform consistency across Mac and iPhone. If you already spend your working day in Apple environments, NetNewsWire removes the need to maintain a separate browser tab or learn a visually unrelated service.

Its limitation is decisive. There's no official Android or web app, so mixed-device households and teams may find the platform boundary inconvenient. The app also depends on the capabilities and availability of whichever sync backend you choose. A native client can't compensate for a backend that lacks the full-text or automation functions you need.

Pick the client first only when your devices are stable. Otherwise, pick the sync service first.

NetNewsWire is ideal for Apple users who value local-feeling performance and open-source software. It's less suitable for people who work across Windows, Android, and browser sessions or who need powerful server-side rules. In those cases, Feedly, Inoreader, or a compatible backend may matter more than the client itself.

8. Reeder

Reeder is built for Apple users who care about design, navigation, and a unified reading timeline. It brings RSS, read-later workflows, sharing extensions, and third-party backends into an elegant interface. The result is less utilitarian than NetNewsWire, which makes Reeder attractive when the reading experience itself affects whether you return each day.

It supports external services and iCloud synchronization for key data, so you aren't limited to one backend model. Reeder Classic offers a one-time purchase route, while newer Reeder variants can include subscription-based cross-device features. Those choices give users some flexibility, but they also mean that the exact feature set depends on which version and account arrangement they select.

Best for a polished Apple reading system

Reeder is especially good for readers who save articles as part of a wider system. A clean unified timeline reduces the need to jump between separate feed, read-later, and sharing tools. It also fits a content workflow that starts with scanning and ends with choosing WordPress blog layouts or another publishing task.

The trade-off is platform exclusivity. Reeder is Apple-only, so it won't solve a cross-platform requirement involving Android or Windows. Feature limits also vary between Reeder variants, and the purchase model can make comparisons less direct than with a single-purpose free client.

Reeder works when you want the app to make reading feel effortless and attractive. It isn't the strongest choice for self-hosting, server-side automation, or a browser-first organization system. If the main challenge is getting yourself to read consistently on Apple devices, however, a polished interface can matter more than an exhaustive rules engine.

9. FreshRSS

FreshRSS is the strongest option here for readers who want maximum control and are willing to run the infrastructure. It's a free, open-source, self-hostable web reader that can run on a server or NAS. You manage the installation, storage, updates, and access rather than handing those responsibilities to a hosted vendor.

It supports Linux, Windows, and macOS environments, Docker, and multiple database backends, including MySQL, PostgreSQL, and SQLite. Multiple view modes and an extensions ecosystem let you adapt the interface to different reading styles. Its Google Reader-compatible API also allows third-party clients to connect, which keeps the service from locking you into one web interface.

Best for ownership and extensibility

FreshRSS makes sense for technically comfortable users, privacy-conscious teams, and anyone who wants a stable personal service under their own administration. It can perform well with large feed lists, and its extensibility gives you more room to tailor the workflow than a tightly controlled hosted app. For a WordPress publisher, it also provides a useful private destination for blog updates without requiring a proprietary reader account.

The cost is operational rather than purely financial. You need a server, installation knowledge, update habits, backups, and a plan for secure remote access. Hosting costs depend on your environment, but even inexpensive infrastructure still demands attention. If the server goes down and you don't notice, your reading queue may stop updating without your realizing it.

FreshRSS is not a “set it up once and forget it” product. It rewards people who enjoy managing their tools and frustrates people who want support, automatic upgrades, and a polished mobile experience without configuration.

Self-hosting is a control decision, not a shortcut to less work.

Choose FreshRSS when privacy, ownership, extensibility, and client compatibility outweigh convenience. Choose a managed service when maintaining another application would become the reason you stop reading.

10. Feedbro

Feedbro is a browser-first RSS and Atom reader for people who discover sources while browsing. Its Chrome and Firefox extensions make adding a feed from the page in front of you quick, and it includes a full-page reader for a more comfortable view. A Feedbro account can synchronize the reading experience across supported browsers.

The extension model is the product's central advantage. You don't need to open a separate application every time you find a useful publication. You can capture it while researching, then return to the queue later. Rules and filters add automation, while server-side AI summaries are available as service features.

Best for browser-based capture

Feedbro works well for researchers, marketers, and writers whose RSS list grows out of daily web discovery. The free plan lowers the entry barrier, and support across major browsers makes it easier to use on different desktop environments. It's also a practical choice for someone who doesn't want to maintain a separate mobile or desktop reader.

The limitations follow directly from the extension architecture. Heavier or faster-fetch functions require the paid Coffee Club plan, and your experience depends on browser extension availability and support. A browser update, organizational policy, or unsupported environment can affect access more directly than it would with a dedicated native app.

Feedbro is best when capture speed matters more than a tightly integrated cross-device system. It won't be the ideal replacement for a full self-hosted service, a polished Apple client, or an advanced enterprise monitoring platform. It does, however, make the basic action of turning a discovered page into a feed subscription unusually direct.

Top 10 RSS Feed Readers, Feature Comparison

ServiceCore features ✨UX/Quality ★Value/Price 💰Best for 👥Standout 🏆
FeedlyFolders/tags, AI summaries, newsletter→RSS, integrations ✨★★★★☆💰 Freemium, AI on higher tiers👥 Individuals & teams🏆 Discovery & ecosystem
InoreaderRules/filters, web feeds, socials & podcasts, mobile rules ✨★★★★☆💰 Freemium, advanced paid tiers👥 Power users & automators🏆 Automation & multi-source aggregation
FeedbinFull-text extraction, newsletter capture, podcast support ✨★★★★☆💰 Paid-only (ad‑free)👥 Privacy-minded readers, native app users🏆 Clean, chronological reading
NewsBlurTrainable filters, text extraction, native apps, self-host ✨★★★★☆💰 Freemium + self-host option👥 Users wanting self-hosting & control🏆 Self-hosting & transparent pricing
The Old ReaderGoogle Reader–style UI, social sharing, premium search ✨★★★☆☆💰 Freemium (limited free tier)👥 Users preferring simple, social web UI🏆 Familiar, uncluttered interface
BazQux ReaderFull-text conversion, in‑reader comments, social monitoring ✨★★★★☆💰 Paid (trial available)👥 Speed-focused, privacy-minded users🏆 Fast UI + in-reader comments
NetNewsWireNative macOS/iOS app, iCloud sync, backend support ✨★★★★★💰 Free & open-source👥 Apple-centric users🏆 Native performance & iCloud sync
ReederElegant UI, unified timeline, read‑later & share extensions ✨★★★★★💰 Paid (one-time/subscription options)👥 Apple users who want polish🏆 Design & ergonomics
FreshRSSSelf-hostable (Docker), extensions, Google Reader API ✨★★★★☆💰 Free (self-host; hosting cost applies)👥 Self-hosters & privacy-focused admins🏆 Extensibility & scale
FeedbroBrowser extension, full-page reader, rules & AI summaries ✨★★★★☆💰 Freemium (Coffee Club paid features)👥 Browser-centric users🏆 In-page feed discovery & quick add

Choose the Reader You Will Actually Maintain

The right choice becomes clearer when you map the reader to the job rather than to a feature count. Feedly or Inoreader are the practical shortlist for discovery, mixed sources, newsletter capture, and automation. Feedly is easier to enter and works well across a broad ecosystem. Inoreader is the stronger choice when rules, filtering, web feeds, and multi-source monitoring will carry much of the workload.

Choose Feedbin or BazQux Reader for focused paid reading. Feedbin offers a clean service with strong native-app compatibility and full-text extraction. BazQux Reader is more minimalist and puts unusual emphasis on speed, privacy, full-text conversion, and comments inside the reader. Neither is the right answer if a permanent free plan is essential.

NewsBlur fits readers who want trainable filtering and a possible self-hosting route without committing to that route immediately. The Old Reader is better for a familiar, simple web experience, especially if you prefer straightforward chronological reading over extensive automation. For Apple users, NetNewsWire or Reeder should be the first comparison. NetNewsWire favors open-source utility and flexible backends, while Reeder emphasizes polished design and a unified reading experience.

FreshRSS is the maximum-control option. It makes sense when you're comfortable with servers, backups, extensions, and maintenance. Feedbro is the browser-first choice for capturing sources as you research, particularly when installing and maintaining a separate app would add unnecessary friction.

A practical setup sequence keeps the decision reversible:

  • Start with a small source set: Add Read More Info's main feed and, if discussion monitoring matters, its comments feed.
  • Create useful folders only: Separate work, research, publishing, and personal reading if those categories change what you do next. Don't build a taxonomy for its own sake.
  • Test full-text behavior: Open several articles from different publishers and check whether the reader keeps you inside the reading view or sends you back to the source site.
  • Check refresh and sync: Read an item on one device, then confirm that its state appears correctly on another device or client.
  • Review the queue after several days: Remove sources you skip repeatedly before importing more. A smaller queue you trust is more valuable than a large queue you avoid.

If you publish through WordPress or manage feeds for a team, test the workflow from both sides. A publisher can use Scheduler.social's RSS setup for Outlook when feed delivery needs to connect with an inbox-based process. A reader should also verify that the feed exposes the content and discussion updates they want, rather than assuming every endpoint behaves identically.

RSS remains useful because it gives readers a predictable, chronological way to follow chosen sources. One study reported that only 12% of users knew about RSS, while 4% knowingly used it and 27% consumed it indirectly through personalized start pages. Among direct users, the average subscription load was 6.6 feeds, with 4.1 hours per week spent reading them. The study summary also shows why reader design matters: the best product is the one that makes your particular queue manageable.

Start with the platform you use every day, then judge the filtering model, full-text behavior, cost, privacy position, and maintenance demands. The best RSS feed reader isn't the one with the longest feature list. It's the one that fits your actual routine closely enough that you keep opening it.


Read More Info publishes accessible WordPress posts and updates with a standard content feed, a separate comments feed, search, and a responsive reading experience. Use it as a practical test source while comparing readers, then visit Read More Info to explore the site and follow future updates.

10 Best Feed Reader Android Apps for 2026

The popular advice says the best feed reader Android users can choose is the app with the most downloads, the highest store rating, or the longest feature list. That approach misses the actual decision. A reader that excels at cloud discovery may be poor for private, offline reading, while a lightweight local app may frustrate anyone who needs cross-device sync, newsletters, or advanced monitoring.

This comparison evaluates ten Android feed readers by the reading problem they solve. The practical criteria are Android usability, synchronization, feed handling, full-text access, offline behavior, privacy, paid limits, notification control, and setup effort. The list includes cloud services, local apps, open-source clients, self-hosted backends, discovery tools, filtering systems, and knowledge-capture workflows.

RSS still connects readers to a very large open web. BuiltWith trend data records 38,136,800 live websites using RSS and 86,771,786 total websites identified as RSS customers, which helps explain why Android readers remain useful despite the decline of individual reader apps. RSS trend data also puts the category in context: the value is aggregation across many publishers, not dependence on one closed platform.

Read More Info is a useful example of the publishing model. It's a lightweight WordPress publication with public content and comments feeds, so you can test how a reader handles both articles and discussion updates. If you're also building a publication, practical feed clickthrough rate tips can help turn subscriptions into visits.

Table of Contents

1. Feedly

Feedly is the safest recommendation for readers who want a polished cloud service without spending time configuring every part of the system. Its Android app works alongside web, desktop, and iOS access, and the interface makes it easy to discover publications, arrange folders, save articles, and return to unfinished reading.

Best for discovery and cross-device continuity

Feedly is particularly effective when your reading list changes often. Discovery tools help you find sources by topic, while filtering and mute controls reduce repeated or irrelevant coverage. Newsletter ingestion, RSS Builder tools, automations, and integrations extend the service beyond ordinary feed reading, especially for research and content workflows.

The trade-off is control. You'll need an account, and the most powerful filtering, search, newsletter, and automation capabilities sit behind paid plans. Offline reading is also less compelling than in Android-first apps designed around local caching.

Practical rule: Choose Feedly when convenience across devices matters more than keeping every subscription and article entirely on your phone.

For a non-technical user, Feedly's onboarding is easier than assembling a self-hosted stack. It's also a sensible front end for a WordPress blog because public RSS feeds can be added without special publishing work. Choose it for polished discovery, integrations, and organizational scale, not for a local-only privacy model.

Feedly

2. Inoreader

Inoreader suits people who treat RSS as a monitoring system rather than a casual newspaper. The Android app connects to the service's web and iOS clients, keeping subscriptions, folders, saved items, and reading decisions available across devices.

Best for rules and site monitoring

Its strength is granular control. Rules can route articles, apply tags, trigger automations, or separate high-priority material from general reading. Inoreader can also follow websites without conventional RSS feeds and turn newsletters into feeds, which is valuable when important sources publish inconsistently.

That flexibility creates a steeper learning curve. A casual reader may find the settings excessive, while advanced features and higher limits require Pro or Team plans. Plan structures have evolved, so check the current terms before building a workflow around a particular capability.

For monitoring, Inoreader is more suitable than a simple local reader because the service can watch sources and process incoming material continuously. It's a strong fit for analysts, editors, marketers, and anyone tracking competitors or niche topics. It can also handle a publication such as the Read More Info blog as one source within a larger monitoring system.

Use Inoreader when: Your problem is not finding feeds, but deciding what should trigger an alert, receive a label, or disappear from the main queue.

The app is powerful, but it can make reading feel like administration if you only follow a small group of sites.

3. NewsBlur

NewsBlur is a veteran reader for people who want filtering that learns from their reading without handing the entire experience to an opaque algorithm. It has native Android and iOS apps plus a web interface, so it works for users who move between phone and computer.

Best for human-guided filtering

NewsBlur's intelligence training lets you indicate which stories, topics, and sources deserve attention. That approach is useful when a feed is valuable but noisy. Instead of abandoning the source, you can teach the service which patterns matter and use different views to move between the original page, a readable text version, and an expanded article.

The “Read the Full Story” behavior is important for feeds that publish excerpts. The “Original Site” view provides a fallback when extraction doesn't work. Per-feed mobile notifications are also practical for a small number of high-priority sources, although enabling alerts for everything quickly recreates the interruption problem RSS is supposed to solve.

Premium plans are needed for capabilities such as broad full-text search and larger site counts. That's a reasonable trade if you value a straightforward service model, but less attractive if you want a completely local setup.

NewsBlur works best when you want privacy-minded filtering and dependable reading modes rather than a large automation platform. It's less focused on newsletter ingestion and knowledge management than Feedly or Readwise Reader, but it handles imperfect feeds with useful flexibility.

4. Readwise Reader

Readwise Reader is not merely an RSS inbox. It combines feeds with newsletters, saved web pages, PDFs, and EPUBs, then gives you tools for highlighting, annotation, review, and export.

Best for turning reading into knowledge

The distinction matters. A conventional feed reader helps you process headlines and articles. Readwise Reader is designed for the next step, when you need to preserve an argument, mark a passage, or move research into Obsidian, Notion, or another notes system.

Its Android, iOS, desktop, and web access make the workflow portable. Offline controls help when you want to prepare a reading queue before commuting, while article highlights and annotations remain useful after the original feed item leaves the front page. AI-assisted reading and review can support summarization, but the core value is still the annotation pipeline.

The cost is higher than that of a basic RSS app. After the free trial, Readwise requires a subscription, so it's difficult to justify if you only want a stream of headlines. It also introduces more concepts than a minimal reader, including document types, highlights, exports, and review workflows.

Reading insight: If you regularly save articles but rarely revisit them, a reader with strong annotation and review tools may solve a bigger problem than a faster inbox.

Choose Readwise Reader for knowledge capture, research, and long-form reading. Choose something else if privacy, local storage, or a no-account setup is your primary concern.

Readwise Reader

5. Feeder

Feeder keeps the reading experience focused. Its Android app emphasizes straightforward subscriptions, quick updates, push notifications, OPML import, and a clean interface rather than a broad ecosystem of research features.

Best for alerts without excessive complexity

Feeder is a good choice when a feed matters because it publishes timely updates. You can configure notifications around selected sources instead of relying on a general news app's algorithm. That makes it useful for release notes, industry announcements, company blogs, and publications where missing a new item has a practical cost.

The setup is uncomplicated, and the plan structure is easy to understand. Team-friendly features add value for shared workflows, while frequent polling and larger limits are reserved for higher plans. If you follow a large number of feeds or need extensive history, those limits deserve attention before you commit.

Feeder's privacy-minded positioning makes it more appealing than a reader built around social recommendations. Still, it's a cloud service, so it isn't the same as a local-only reader with no account. Faster updates and advanced capabilities may also require payment.

A strong implementation starts with a small set of alert-worthy feeds. Use ordinary feeds for background reading, then reserve push notifications for sources that justify immediate attention. That distinction keeps Feeder useful instead of turning it into another notification channel.

Feeder

6. FeedMe

FeedMe is the practical pick for Android users who care about offline reading, speed, and backend flexibility more than visual polish. It can work locally with OPML imports or connect to services including Feedly, Inoreader, BazQux, The Old Reader, Tiny Tiny RSS, and FreshRSS.

Best for commuters and heavy skimmers

FeedMe's offline behavior is its clearest advantage. You can download articles and images before leaving a reliable connection, then read through a queue without waiting for every page to load. Text-to-speech and gesture controls make it suitable for hands-free listening or fast, one-handed triage.

An independent Android benchmark found FeedMe had the fastest sync latency among eight actively maintained clients, with a median 1.42 seconds from feed-update notification to a fully rendered article list across 500 RSS sources on Android 14 using identical Pixel 7 Pro devices. The same benchmark measured 11.8 MB RSS idle RAM for FeedMe, compared with 41.5 MB for Feedly. The benchmark details make memory and responsiveness meaningful selection criteria for mid-range phones and busy background-app environments.

A separate task-completion evaluation found that a highly rated reader took 4.83 seconds on average to display and scroll to the first full paragraph, more than 2.6 times slower than FeedMe, while using 217 MB of RAM during background sync. That Android evaluation illustrates why store ratings don't always predict reading speed or resource cost.

The compromise is an utilitarian interface. FeedMe rewards configuration and repeated use, but it won't feel as immediately refined as Feedly.

FeedMe (by Seazon)

7. FocusReader

FocusReader concentrates on the Android reading surface. Its Material interface, gesture navigation, readability options, translation tools, and per-feed full-text controls make it appealing when the act of reading matters more than administration.

Best for comfortable full-text reading

The app supports a broad range of backends, including Feedly, Inoreader, The Old Reader, Feedbin, BazQux, Tiny Tiny RSS, FreshRSS, and Fever. That gives you a polished front end without forcing you to abandon a service or self-hosted system you already trust.

Its readability pipeline is useful for difficult feeds. A publisher may provide only a short excerpt, use cluttered markup, or format its page in a way that performs poorly inside ordinary readers. FocusReader can offer a more consistent article view and translation when language is part of the reading workflow.

The trade-off is business-model friction. Some capabilities require in-app purchases, and development may feel less predictable than with larger hosted services. You'll also want to test the feeds that matter most, because full-text extraction can vary by publisher.

FocusReader fits readers who spend substantial time inside the Android app and want gestures, typography, and navigation to feel deliberate. It's less suitable if you want a completely local, account-free reader.

8. Read You

Read You takes the local-first route. It's a free, open-source Android reader built with Kotlin and Jetpack Compose, using a Material You design that feels current without requiring a cloud account.

Best for local control and simplicity

Read You manages feeds locally and supports OPML import and export. That's enough for readers who want to subscribe, browse, save a small number of items, and keep control of where subscriptions live. Distribution through F-Droid and GitHub also suits users who prefer open-source release channels.

The absence of sign-in is the central benefit. You don't have to create another service account, hand subscriptions to a hosted provider, or accept a cloud layer merely to read public feeds. That makes Read You a strong fit for privacy-conscious users who read primarily on one Android device.

There's a real limitation, though. Built-in service integrations are narrower than those of Feedly, Inoreader, FeedMe, or FocusReader. If you switch frequently between phone and desktop, need server-side search, or want a shared reading state, local simplicity can become manual work.

Choose local storage when: Your priority is reducing dependence on a service, and you're comfortable giving up some cross-device convenience.

Read You is not the most powerful app in this list. It's one of the clearest answers for lightweight, private, account-free RSS reading.

9. Readrops

Readrops sits between a local app and a commercial cloud reader. It's open source, supports local use, and connects to self-hosted services such as FreshRSS and Nextcloud News.

Best for self-hosted synchronization

This is the right direction for readers who want multi-device sync without placing their subscriptions in a large commercial platform. Your server becomes the source of truth, while Readrops provides the Android interface for reading, sorting, and keeping progress consistent.

The setup requires more ownership than Feedly or Feeder. You need a compatible backend, a working server, and a willingness to handle updates and troubleshooting. That effort is worthwhile for users who already run FreshRSS or Nextcloud, but it's unnecessary for someone who only wants to follow a few public blogs.

Readrops has a Material 3 redesign and Android 14 compatibility, and it's distributed through F-Droid, GitHub, and the Play Store. Its open-source model reduces vendor lock-in and keeps software costs near zero, although a smaller development team can mean that bug fixes and feature changes take longer than they do in a commercial product.

Use Readrops when private sync is the problem. Use Read You when local reading is enough. Use FeedMe when you need to connect to several kinds of hosted or self-hosted backends from one Android client.

10. Fluent Reader Lite

Fluent Reader Lite is aimed at readers who want a clean mobile companion to the Fluent Reader desktop ecosystem. Built with Flutter for Android and iOS, it keeps the interface lightweight and avoids the density of a monitoring platform.

Best for a minimal cross-platform setup

OPML import makes the initial move straightforward, while simple full-text reading handles the basic job of opening articles without sending you through a maze of options. Regular releases and public issue tracking provide useful visibility for open-source users.

Fluent Reader Lite works well when your needs are modest: follow feeds, read items, keep a consistent experience between desktop and mobile, and avoid unnecessary account layers. It isn't designed to replace Inoreader's rules or Readwise Reader's annotation system.

That limited scope is both the attraction and the weakness. Heavy users may miss deeper filtering, richer offline controls, advanced notifications, or broad backend integrations. A minimalist app can also feel incomplete if your reading workflow has grown into research, team sharing, or content automation.

For a small personal feed list, Fluent Reader Lite is refreshingly direct. It's especially suitable for people who already use Fluent Reader on desktop and want the same general philosophy on their phone. It also pairs naturally with a publication built around simple WordPress blog layouts, where clear content matters more than a complex reading interface.

Top 10 Android Feed Readers, Comparison

ReaderCore features ✨UX / Quality ★Price / Value 💰Best for 👥Standout 🏆
FeedlyAndroid/web/iOS, AI filters, newsletter→RSS, many integrations★★★★ polished, easy onboarding💰 Freemium (Pro/Pro+/Enterprise)👥 Non-technical users & teams🏆 Discovery & integrations
InoreaderRules/automations, web feeds, fast updates, newsletter→feed★★★★ power-user controls💰 Freemium (Pro/Team for higher limits)👥 Power users & site monitors🏆 Granular filters & rules
NewsBlurIntelligence training, per-feed notifications, Original/Text view★★★★ privacy-minded, reliable mobile💰 Affordable paid tiers, transparent👥 Privacy-focused readers🏆 Flexible view modes & feed expansion
Readwise ReaderRSS + newsletters + PDFs, highlights, exports to Obsidian/Notion★★★★ focused on knowledge workflows💰 Subscription after trial (higher-end)👥 Researchers & note-takers🏆 Best highlight/export workflow
FeederFast polling, push notifications, OPML, team features★★★★ minimal, dependable alerts💰 Freemium (Plus/Pro/Enterprise)👥 Users needing timely alerts🏆 Reliable push notifications
FeedMe (Seazon)Excellent offline download, TTS, sync with many backends★★★★ optimized for heavy skimming💰 One-time / affordable paid app👥 Commuters & offline readers🏆 Best Android offline experience
FocusReaderMaterial UI, readability/full‑text, translation, many backends★★★★ polished, fast navigation💰 Free + in-app purchases👥 Android users switching services🏆 Readability & translation pipeline
Read YouLocal feeds, OPML, Material You, no sign-in (FOSS)★★★★ clean, lightweight💰 Free & open-source👥 Privacy-preferring local users🏆 No-account, open-source simplicity
ReadropsMulti-backend (FreshRSS/Nextcloud), Material 3, FOSS★★★★ self-host friendly💰 Free & open-source👥 Self-host/FreshRSS users🏆 Seamless self-hosted sync
Fluent Reader LiteCross-platform mobile, OPML, simple full-text reading★★★★ distraction-free, consistent💰 Free & open-source👥 Users pairing with desktop app🏆 Lightweight mobile + desktop parity

Choose the Reader You Will Actually Use

The best feed reader Android users can choose depends on where reading friction appears first. Feedly is the practical starting point for polished discovery, easy onboarding, cross-device sync, and integrations. Inoreader is better when you need rules, monitoring, web feeds, newsletter ingestion, and granular automation.

Choose NewsBlur if you want human-guided filtering, flexible article views, and a privacy-minded service model. Choose Readwise Reader if the important result isn't marking an article read, but extracting an idea, annotating a passage, and moving it into your knowledge system.

Feeder is the notification-focused option. It's a good fit for readers who want dependable alerts and a straightforward interface without turning every subscription into a complicated workflow. FeedMe is the strongest choice for heavy Android reading, offline queues, backend interoperability, and efficient skimming.

FocusReader suits users who care about reading comfort, readability tools, translation, and the freedom to connect different backends. Read You is the clean local open-source option for people who don't want an account. Readrops is the better answer when you want private synchronization through FreshRSS or Nextcloud News. Fluent Reader Lite works for a minimal mobile experience that complements its desktop ecosystem.

RSS also remains a practical open publishing layer. WordPress sites include built-in feeds, and adding /feed/ to a site address is the standard way to access the main feed. WordPress also provides /comments/feed/ for following discussion activity, while its documentation distinguishes comment-only feeds from feeds containing site content. WordPress feed documentation explains the public endpoint pattern, and the developer documentation for comment feeds covers site-wide and per-post discussion feeds.

Read More Info makes a useful test case because it offers both the main article feed and the comments feed. Add the content feed first, then test whether your chosen app can display article text cleanly, cache it for offline use, preserve unread state, and handle new discussion entries without mixing them into the main reading queue.

Keep the implementation small at the start:

  • Subscribe selectively: Begin with a few reliable feeds instead of importing every source you've collected.
  • Use OPML when moving: Export an OPML file from the old reader when available, then import it into the new app and check folders manually.
  • Test full text: Open several articles from different publishers because extraction quality varies by feed.
  • Test offline behavior: Download a reading queue before leaving Wi-Fi and confirm that images, article text, and saved items behave as expected.
  • Configure notifications carefully: Alert only on feeds where immediacy matters, and leave routine publications for scheduled reading.

The local-versus-cloud decision deserves equal attention. Cloud readers provide convenience, server-side processing, cross-device continuity, discovery, and automation. Local readers reduce account dependence and give you more control, but they may require manual export, separate device setup, or your own server. Neither model is universally superior.

The same evaluation discipline applies beyond RSS. If your wider workflow includes free office tools, free tools, free AI tools online, free OCR tools, free editing tools for videos, free tools for video editing, free daemon tools, free ZIP tools, free Pro Tools download, Pro Tools free download, free keyword tools, free keyword tool, free tools like Photoshop, free budgeting tools, free humanizer tools, free tools online, free wireframe tools, free BI tools, free visualization tools, free writing tools, free drawing tools, free CRM tools, or free map tools, compare each product by the job it removes, not by the number of features shown on its landing page.

Start with the reader you'll open every day. Subscribe to a small set of public feeds, test the experience on your actual Android device, and only then build folders, rules, alerts, or self-hosted infrastructure around it.


Read More Info offers straightforward WordPress posts, public RSS syndication, comments RSS, search, and a responsive reading experience for general audiences. Visit Read More Info to explore the publication and add its open feeds to the Android reader that best matches your workflow.

Understanding the Site Search Function on WordPress

You've probably used a site search function hundreds of times without thinking about it. You open a blog, skip past the navigation menu, type a phrase into the small magnifying-glass box, and wait to see whether the website understands what you need. If the right article appears, search feels invisible. If the page says “Nothing Found,” the same feature suddenly becomes the reason you leave.

For a first-time WordPress publisher, search can look like a tiny design detail. It's more useful to treat it as a small system with several connected parts: a visible input, a method for interpreting the query, an index of available content, a results page, and a way to recover when nothing matches. Once you understand those parts, WordPress's basic search becomes a sensible starting point rather than a feature you need to replace immediately.

Table of Contents

What a Site Search Function Actually Does

A site search function lets visitors look for information inside one website. That makes it different from Google, Bing, or another external discovery tool, which searches across the open web. On a WordPress information site, a visitor might search for a recipe, an explanation, or an older article without knowing which category contains it.

The function usually appears in two visible places. First, there's the search box, often in the header, sidebar, menu drawer, or footer. Second, there's the results page, which lists the posts or pages that the system believes match the visitor's words. The box starts the conversation. The results page either helps the visitor finish it or asks them to try again.

A useful analogy is a library card catalog. The library contains thousands of books, but the visitor doesn't walk through every shelf looking for a title. They search the catalog, receive a set of references, and then choose the result that looks most useful. Your WordPress site has posts instead of books, and its index is digital instead of made from cards, but the principle is similar.

Practical rule: Treat search as a navigation route for visitors who already have a topic in mind, not as decoration for the header.

A diagram illustrating the four key components of a site search function including interaction, processing, delivery, and satisfaction.

Research into custom site-search applications examined 277 captured information needs and found that site-search users were mainly completing simple lookup tasks. The same CEUR-WS study of custom site-search applications found that site-search sessions often formed repeating chains, but those chains were shorter and less complex than enterprise-search sessions. In plain language, a reader usually isn't asking your blog to solve a broad research problem. They often know roughly what they want and expect a quick route to it.

That expectation explains why a search box matters on a content-heavy site. A reader may not remember the article title, but they may remember “sourdough discard,” “budgeting,” or “mobile layout.” Clear site search gives those visitors an alternative to scrolling through archives. If you're unsure how a phrase can be located within a page before planning your own content structure, this guide to locate words on webpages offers a practical reference.

The rest of the system becomes easier to understand once you separate the visitor's action from WordPress's work. The visitor enters a query. WordPress processes it against indexed content. The results page presents matches. Search quality depends on how well those steps fit the visitor's expectation.

How a Site Search Function Works Behind the Scenes

Think of your website as a library that prepares a subject index before anyone walks through the door. WordPress stores information about posts and pages, then uses that stored content when a visitor submits a search. The search function doesn't read every page from scratch in the same way a person would. It sends the query to the site and checks the available records for matching terms.

The four moving parts

Input is the search field where the visitor types a phrase such as “free keyword tools.” The form normally sends that phrase to a search results address through a standard request. A simple form is valuable because it can keep working even when JavaScript is disabled or a theme's interactive features fail.

Query processing takes the submitted words and turns them into a request WordPress can use. In a basic installation, that request checks the searchable post data stored in the WordPress database. WordPress's default search is commonly described as a SQL-style LIKE lookup against the wp_posts table, which means it looks for matching text patterns rather than understanding a visitor's full intention.

Indexing determines which content is available to match. WordPress's built-in search focuses on ordinary post material, including titles, content, and excerpts. A troubleshooting explanation of WordPress search limitations notes that the default system is case-insensitive, but doesn't reliably expand related word forms and doesn't automatically search custom fields, taxonomies, or post meta.

Result delivery is the page the visitor sees after submitting the form. WordPress gathers possible matches, orders them, and displays titles, links, and supporting text. The result is closer to a filing system than to a human editor. It can find repeated words, but it doesn't automatically understand that two different expressions may describe the same idea.

An infographic showing the four steps of how a site search function works behind the scenes.

Why matching isn't the same as understanding

Traditional search ranking can consider where a term appears, how often it appears, and signals such as publication date. A title match may look more useful than a passing mention in the body, but the default system doesn't possess deep semantic understanding. A post about “rainy-day savings” may not appear for “emergency fund” unless the relevant words are present or an extension supplies that relationship.

That distinction becomes important as your archive grows. A lightweight index can be perfectly adequate for a straightforward blog, while a documentation site, recipe site, or product catalog may have useful information stored outside the title and body. If your content needs to connect structured facts with natural-language questions, it can help to study how teams build a working AI knowledge base, while remembering that a small WordPress publisher may not need that complexity yet.

The system also depends on speed. Google reported that adding 100 to 400 milliseconds of delay to search results reduced searches per user by about 0.2% to 0.6% in its research on speed, as described in Google's speed research. For WordPress, that gives a practical reason to keep indexing focused, templates light, and repeated queries efficient. A visitor who receives an unhelpful result slowly experiences two problems instead of one.

Core Features That Shape Search Quality

A useful way to compare search features is to place them in levels. The first level helps the system find ordinary matches. The next level helps visitors narrow and refine those matches. The final level helps you learn what people wanted when the search did or didn't work.

Start with dependable matching

The essential layer is full-text matching across the fields your readers expect. On a basic WordPress blog, that usually means post titles and body content. If your site publishes articles about tools, for example, a visitor searching “free writing tools” should be able to find a relevant post even when the phrase isn't in the title.

Partial-word and fuzzy matching add resilience. A reader may type a misspelled term, use a shortened word, or enter a slightly different form. Without tolerance, one typing error can produce an empty page even though a useful article exists. Relevance ranking then determines which match appears first. Giving stronger weight to a title match than to a single body-text mention generally makes the result list easier to scan.

Add refinement when the archive needs it

Filtering becomes valuable when one query returns several kinds of content. A site might let visitors narrow results by category, tag, or post type. On an archive that includes tutorials, opinion posts, and downloads, a filter can turn a long mixed list into a manageable set.

Autocomplete works earlier in the process. As the visitor types, a small dropdown can suggest common phrases or existing content. It can also help a visitor discover the vocabulary your site uses, which is useful when their first wording doesn't match your headings.

The best feature set depends on the archive, not on how impressive the plugin's settings page looks.

TierFeatureWhat It Changes for Visitors
EssentialTitle and body matchingGives ordinary keyword searches a dependable starting point
EssentialRelevance rankingPlaces stronger matches where visitors are most likely to see them
Quality shapingFuzzy matching and typo toleranceRecovers searches with spelling errors or partial terms
Quality shapingFilters and facetsHelps visitors narrow results by category, tag, or content type
ConvenienceAutocomplete suggestionsOffers useful phrasing before the visitor submits a query
InsightHighlighted terms and analyticsMakes matches easier to scan and reveals recurring content needs

Use the results page as feedback

Highlighted terms in excerpts help visitors see why a result appeared. If the phrase “free map tools” is visible in the excerpt, the reader can judge relevance without opening several pages. Search analytics provide a publisher-side view of the same experience. They can reveal repeated searches, no-result phrases, and topics readers want but cannot find through navigation.

Synonym controls and stop-word settings refine the system further. Synonyms connect terms that mean similar things on your site. Stop-word controls prevent common words from overwhelming the match. These controls need care because an incorrect synonym can make results look broad while reducing their usefulness.

The historical evidence reinforces why refinement matters. A Wiley study recorded 1,025,910 queries from 211,063 users, with 51.8% unique queries, 38.5% repeat queries, and 9.7% zero-query sessions, as reported in the Wiley study of web-search behavior9999:9999%3C::AID-ASI1591%3E3.0.CO;2-R). A Microsoft Research study found that users spent an average of 5.7 seconds considering results before their first selection, with a 95% confidence interval of 4.9 to 6.5 seconds, according to Microsoft's search-results research. A clear first result and a useful refinement path both respect that short decision window.

WordPress Default Search Versus Enhanced Alternatives

WordPress core gives beginners a deliberately minimal search function. It's available without a separate search service, extra indexing process, or plugin dependency. The trade-off is scope. The default system generally searches ordinary post material, while structured information outside that material may remain invisible.

Compare the choice through three dimensions: indexing scope, relevance ranking, and empty-state handling. This is more useful than asking whether one option is “better.”

DimensionWordPress DefaultEnhanced Plugin, such as SearchWP or Relevanssi
Indexing scopePrimarily post titles, content, and excerptsCan extend search to selected custom fields, PDFs, products, and other configured content
RelevanceBasic keyword-oriented matchingCan add weighting, fuzzy matching, and more deliberate ranking controls
Empty-state handlingDepends heavily on the theme's “Nothing Found” templateMay provide suggestions, highlighted terms, filters, or configurable recovery paths
MaintenanceNo additional search plugin to updateRequires indexing management, compatibility checks, and plugin maintenance
Resource demandsLightweight for a simple archiveMore indexing work and potential database or service overhead

Consider a recipe blog with ingredients stored in custom fields. A reader may search for “free budgeting tools” or “free baking tools,” but the important ingredient information may not appear in the post body. An enhanced search system can index that structured information if configured to do so. A support knowledge base may benefit from taxonomy-aware weighting, while a small portfolio may need only an empty-results page that points visitors to project categories.

Plugins such as SearchWP, Relevanssi, and Jetpack Search can extend the areas WordPress searches and add controls for ranking or presentation. The exact behavior depends on the product, its configuration, and whether the content has been indexed correctly. Adding a plugin doesn't automatically create good relevance. Someone still needs to decide which fields matter and test real visitor queries.

The default search is a useful baseline. Replace it only when you can name the content it misses or the visitor behavior it fails to support.

A beginner can first review the site's content structure and empty state. If the archive is small and uses standard posts, the built-in system may be sufficient. If visitors repeatedly search for metadata, attachments, products, or taxonomies, an enhanced alternative becomes easier to justify. Before changing the search, review the broader choices in best WordPress blog layouts so the search placement supports, rather than competes with, the site's navigation.

Implementation Considerations for WordPress Sites

Installing a search widget is only the beginning. A usable implementation combines placement, presentation, performance, and accessibility. Treat those as separate decisions, because a search box can be visible and still be difficult to use.

Put the entry point where visitors look

On desktop, the header is usually a sensible location because visitors can access it from every page. On mobile, the same control may need to live in a menu drawer or a clearly reachable footer area. Don't hide search behind an icon that has no label if your audience may not recognize it.

The field also needs helpful presentation. Placeholder text such as “Search articles” explains the action more clearly than an empty box. A visible submit button can support people who don't use keyboard shortcuts, and a proper label helps screen-reader users understand the field.

Your empty-state page needs equal attention. WordPress may show a “Nothing Found” message when no content matches, but that message shouldn't end the visitor's journey. Explain what the site searches, suggest a broader phrase, and offer links to categories, recent posts, or the homepage.

Keep the index focused

Index published, public content that visitors can open. Excluding drafts, private records, and irrelevant post types prevents the results from promising access to something unavailable. You may also want to exclude repeated boilerplate, shortcode output, or template text that can create misleading matches.

Performance matters even on a lightweight theme. Limit unnecessary searchable fields, cache frequent queries where appropriate, and monitor whether an enhanced index adds database work. A simple site doesn't need an elaborate search architecture, but it does need a search process that doesn't make every result request heavier than necessary.

Preserve access without JavaScript

The input should have a visible label or an appropriate aria-label. Results should be reachable with a keyboard, and focus should move predictably when interactive suggestions appear. The no-JavaScript fallback should still submit a normal GET form and return a results page, so the feature remains useful under different themes, caching layers, and browser settings.

Responsive behavior is part of the same implementation. MDN's responsive design guidance explains why the viewport meta tag belongs in the document head and how width=device-width lets mobile browsers use the device's actual width. MDN's media-query guidance warns that without the viewport setting, a browser may treat the page as roughly 980 pixels wide rather than using the device's actual width. A search field that works on a desktop but becomes tiny or off-screen on a phone isn't complete.

For a broader beginner-friendly foundation, this guide to how to create a WordPress blog can help you consider search alongside themes, content organization, and publishing basics.

A Real Search Session Walk Through an Example

A hobby bakery blog has about 80 posts covering sourdough, cakes, bread storage, and kitchen basics. A visitor arrives on a recipe article, scans the header, and types “sourdough discard recipes” into the search box. The WordPress form submits the phrase, the default query checks the searchable post records, and the results page returns five posts in under a second in this example.

The visitor opens the second result because its title and excerpt mention the exact kind of recipe they want. That first search succeeds because the phrase appears in ordinary post content and the results page gives enough context to compare the matches. The visitor then searches for “newsletter signup” because they want to receive future recipes.

No result appears. The signup page is stored as a draft or uses a non-public post type excluded from the search query, so the system cannot show it. Consequently, the empty-state page decides what happens next. A blank message sends the visitor away, while a useful recovery path gives them another chance to discover the publication.

A person using a laptop to search for sourdough discard recipes on a website.

The bakery owner improves the “Nothing Found” template by adding popular categories, recent posts, and a link to the site's RSS feed. The visitor may not find the signup page through search, but they can still open another recipe, browse the archive, or subscribe through a feed reader. The empty page becomes a discovery surface rather than a dead end.

RSS is useful here because it serves a different habit. Britannica describes RSS as a format for delivering new content from frequently updated websites to subscribers through an RSS reader or aggregator. The RSS Board also describes RSS as an XML-based format for syndicating web content across client software. Search helps someone retrieve an existing article. RSS helps someone track future updates without returning to the homepage manually.

This small journey shows why the site search function shouldn't be judged only by successful queries. The failed query reveals an indexing or expectation problem, while the recovery page determines whether the visitor can continue. Search and feeds support different stages of content discovery, and a simple WordPress site can offer both without turning into a complex application.

Your Site Search Function Checklist and Next Steps

A beginner can improve search without changing everything at once. Use three decision groups, then revisit each group when the site's content or visitor behavior changes.

Placement and visibility

Put the search box in the desktop header or another location visitors can reach from every page. Make it available from the mobile menu, use a clear label, and test it on a phone. Revisit this decision when people report that they couldn't find search or when a theme redesign changes the header.

Functionality and recovery

Search your own site with ordinary phrases, misspellings, category names, and terms that appear only in structured fields. Confirm that results show published content, that ordering feels sensible, and that the “Nothing Found” page offers categories, recent posts, or a broader search suggestion.

You can use these example queries to test different content needs:

  • Free office tools
  • Free tools
  • Free AI tools online
  • Free OCR tools
  • Free editing tools for videos
  • Free tools for video editing
  • Free daemon tools
  • Free zip tools
  • Free pro tools download
  • Pro tools free download
  • Free keyword tools
  • Free keyword tool
  • Free tools like Photoshop
  • Free budgeting tools
  • Free humanizer tools
  • Free tools online
  • Free wireframe tools
  • Free BI tools
  • Free visualization tools
  • Free writing tools
  • Free drawing tools
  • Free CRM tools
  • Free map tools

These phrases also show why exact-word matching can be restrictive. A visitor may use singular and plural forms, add “online,” or search for a product phrase that your article expresses differently. Revisit the default search when these tests repeatedly return empty or poorly ordered results.

Growth and optimization

Start with WordPress's built-in search if your site uses standard posts and the results meet your readers' needs. Consider SearchWP, Relevanssi, Jetpack Search, or another suitable extension when you can identify a specific gap, such as custom fields, PDFs, taxonomies, product data, fuzzy matching, or better analytics.

Keep a record of no-result searches and recurring reformulations. Revisit your categories and tags when visitors use terms that your site doesn't use, and consider an enhanced search system when the archive becomes harder to browse manually.

For more WordPress publishing guidance, explore the Read More Info blog and apply one improvement at a time. A visible search box, honest indexing scope, useful empty-state guidance, and a lightweight results page are enough to create a strong foundation before you consider advanced features.


Read More Info offers practical WordPress articles and updates for readers who want straightforward guidance on publishing, discovery, and site management. Visit Read More Info to find more advice for building and improving a clear, useful content website.

10 Responsive Template for Website Picks

A mobile-friendly demo can still be a poor foundation for a real publication. A polished homepage says little about how a theme handles long articles, category archives, search results, empty states, RSS-friendly publishing, image sizing, or future maintenance. It also says little about whether editors can work comfortably in the block editor or whether every meaningful change depends on a page builder.

That distinction matters for a lean WordPress publication such as Read More Info. WordPress provides site-wide feeds at /feed/ and comments feeds at /comments/feed/, while archive, search, category, author, and other content feeds can also be exposed through standard feed URLs, as documented by WordPress feed documentation and WordPress.com feed guidance. A responsive template for website use must preserve those publishing paths, not just resize a hero section.

This list compares ten options by editing model, customization depth, likely overhead, responsive controls, portability, limitations, and real implementation checks. Responsive design is now a near-universal baseline, with an industry summary placing adoption at around 90% of websites worldwide, or roughly 1.2 billion websites, in the 2025-2026 period reported industry summary. The better question is which foundation remains readable, fast, accessible, and manageable after launch. That same principle applies to mobile-first design for law firms, where clear content access matters more than visual novelty.

Table of Contents

1. Astra by Brainstorm Force

Astra by Brainstorm Force

Astra is a strong general-purpose choice when a publication needs a clean blog today and more flexible landing pages later. Its performance-first approach keeps the theme from dictating every visual decision, while layout, typography, color, container, and sidebar controls give editors enough room to shape a recognizable publication.

The practical advantage is compatibility. Astra works with Gutenberg, Elementor, Spectra blocks, and a broad starter-site library, so a site can begin with the block editor and add more specialized layouts without immediately rebuilding its foundation. Header and footer builders, blog layout controls, and granular width settings are useful when the homepage, archives, and individual posts need different levels of density.

For Read More Info, I'd start with a restrained blog layout, then test the Read More Info blog on narrow screens before importing decorative elements. The theme can support a straightforward reading experience, but its large settings surface can invite unnecessary customization.

Where Astra works well

  • Lean publishing: It can produce a clean article-first layout without forcing a visual builder.
  • Future expansion: Landing pages, portfolios, or commercial sections can be added without abandoning the theme.
  • Responsive control: Container widths, sidebars, headers, and typography can be tuned rather than accepted as fixed defaults.

The trade-off is that many power-user controls sit behind the Pro addon, and the breadth of settings can slow down beginners. Keep the design system small, avoid stacking starter templates with extra plugins, and verify that search, archive, and “Nothing Found” states remain coherent.

2. GeneratePress

GeneratePress is the option I'd choose when predictable markup and low overhead matter more than visual spectacle. It starts almost bare, which can feel underwhelming in a demo, but that restraint becomes valuable on a content site where the article, navigation, and archive structure should carry the experience.

Its close relationship with GenerateBlocks makes it especially suitable for block-editor workflows. Editors can build reusable sections with core WordPress concepts instead of locking every page into a proprietary builder canvas. GeneratePress Premium adds the theme builder, advanced typography, and starter sites, while the free foundation remains useful for a lean publication.

A new site may need deliberate configuration before it looks distinctive. That isn't a flaw, but it changes the work involved. You'll need to establish container widths, heading scale, post metadata, archive spacing, and navigation behavior rather than relying on a highly art-directed import.

Best use in a publishing workflow

GeneratePress suits writers, editors, and small teams that value stable templates over endless visual options. It's a particularly sensible base for a WordPress blog creation workflow because the editor can focus on posts while the theme supplies a controlled structure.

Its accessibility-oriented approach and attention to Core Web Vitals are useful starting points, but no theme can guarantee a fast result after images, analytics, advertising, and embeds are added. Test the actual homepage and post template, not an empty installation.

Practical rule: If a design requires a builder for every paragraph, it probably isn't lean enough for a publication whose main product is readable text.

The limitation is customization depth without paid modules or GenerateBlocks. That cost can be worthwhile when it replaces a heavier builder stack, but beginners should expect a setup phase rather than instant visual polish.

3. Kadence Theme by Kadence and Nexcess

Kadence Theme by Kadence and Nexcess

Kadence takes a blocks-first approach but feels more designed out of the box than GeneratePress. Its typography, spacing, and starter templates can get a small business or content publication to a professional appearance quickly, which reduces the temptation to assemble a page builder and several visual add-ons.

The header, footer, and mega-menu builders provide meaningful control over site-wide navigation. Global design settings help keep headings, buttons, and content sections consistent, while dynamic content sources and optional integrations support a site that may later add WooCommerce, memberships, popups, or testing tools.

That growth path is also the main consideration. The current Kadence offering is consolidated under Liquid Web and Nexcess, with bundle structures that connect additional marketing, membership, and security tools to annual plans. Those options can be useful for an all-in-one stack, but a simple blog may pay for breadth it won't use.

What to test before committing

Install only the modules required for the publication. Then inspect:

  • Header collapse: Confirm that the mobile menu remains obvious and usable.
  • Archive density: Check whether post cards preserve clear titles and excerpts without excessive decoration.
  • Editor output: Publish a real article containing headings, lists, images, links, and embeds.
  • Growth features: Decide whether optional commerce or conversion tools belong in the theme layer at all.

Kadence is a good fit when polished visual setup and future business functionality outweigh the simplicity of a minimal theme. It can feel heavier than an ultra-lean foundation if every module is enabled, so treat its optional ecosystem as a menu, not a requirement.

4. Neve by Themeisle

Neve is built for quick, flexible WordPress launches. Its blog and magazine-friendly templates make it easier to move from an empty installation to an attractive publication, while Gutenberg support keeps the editing model accessible to teams that don't want every page to depend on Elementor.

The theme offers multiple blog layouts, archive controls, and starter sites for both the block editor and Elementor. That flexibility is useful for a small business owner who may publish articles now and add a course, store, or service section later. It also creates a decision point: choose the editor you want to maintain before importing a design that assumes another one.

Neve's performance module is relevant because responsive behavior alone doesn't guarantee a good mobile experience. WordPress accessibility guidance describes responsive design as automatic adjustment across phones, tablets, and desktop computers, and recommends testing themes across browsers and screen widths. Neve should be tested the same way, with real content rather than placeholder blocks.

The maintenance trade-off

Neve is attractive for beginners because it reduces the time needed to establish typography, spacing, and page hierarchy. Some of the strongest layout controls and templates are Pro-only, while displayed promotional prices may renew at the full rate. Treat that commercial structure as part of the technical decision, not as a separate purchasing detail.

It's a practical choice for a site that needs visual momentum without committing to a highly specialized builder. Keep the template light, limit add-ons, and verify that the post, category, search, and empty states all use the same visual language. A responsive template for website use should make those less glamorous screens feel intentional too.

5. Blocksy by CreativeThemes

Blocksy by CreativeThemes

Blocksy balances a feature-rich free version with a modern Customizer experience. It's a strong candidate when a publication needs more than typography and spacing, but the team still wants to work primarily with Gutenberg instead of building every template in a visual editor.

Its header and footer builder, content hooks, and blog enhancements give editors control over the parts readers use. Related and trending posts, reading-time displays, dark mode, and flexible content areas can improve discovery when they're applied carefully. WooCommerce extensions, including filters and floating-cart options, make Blocksy more adaptable if the site grows into commerce.

The free version is unusually capable, but that doesn't mean every option belongs on a lean publication. More controls create more ways to produce inconsistent templates. A related-post module can help an archive, for example, but it can also push the primary article below the fold if spacing and image sizes aren't managed.

A useful balance for growing sites

Blocksy suits creators who want a clear interface and room to experiment. Its UI is friendlier than many multipurpose themes, and the theme is maintained with speed in mind. Pro-only add-ons still create boundaries, especially around advanced site-wide features and white-label workflows.

Use a real content sample before finalizing the design. Test a short post, a long post, an image-heavy post, and a search result with no matches. Make sure touch targets remain easy to use, headings wrap naturally, and dark mode doesn't reduce contrast.

The best use of Blocksy is selective customization. Enable the tools that improve navigation or reading, then leave the rest off. That approach preserves the theme's flexibility without turning a simple publication into a collection of competing modules.

6. OceanWP

OceanWP

OceanWP remains a useful choice for people who want fine-grained Customizer control without writing code. It has long supported multipurpose sites, and its extensive controls cover blog archives, single posts, search pages, 404 pages, headers, footers, and many individual page elements.

That breadth helps when a publication has unusual requirements. You can shape the post metadata, sidebar behavior, featured images, and archive structure with more precision than a minimal theme typically provides. Ocean Extra adds functionality, while the demo and extension ecosystem gives Elementor users a fast route to a traditional blog layout.

The risk is configuration sprawl. A site can accumulate extensions because each one solves a narrow visual problem, then lose the performance and maintenance advantages that made a theme attractive in the first place.

Responsive isn't the same as usable. A page can shrink correctly while its menu, form controls, images, and search state remain frustrating on a phone.

OceanWP is best for teams willing to make deliberate decisions about which extensions are active. Review the plugin list after the initial setup, remove demo content and unused components, and inspect the generated page at phone and desktop widths. Check horizontal scrolling, keyboard focus, image cropping, and the behavior of the 404 and no-results pages.

Pricing and plan details are distributed across documentation and checkout, so record the license assumptions before building a site that depends on premium extensions. OceanWP gives you control, but the operator must supply discipline.

7. Hello by Elementor

Hello is not a traditional content theme. It's an ultra-minimal blank canvas designed to hand almost all presentation work to Elementor. That makes it predictable for a custom build, especially when a designer wants the theme to add as little styling and markup as possible.

The free theme is available through the WordPress repository and has a tiny footprint. Elementor's Theme Builder then supplies templates for headers, footers, archives, posts, search results, and other site-wide structures. This separation can be clean when one person owns the design system and understands the builder.

It's less comfortable for a beginner who expects a complete blog experience immediately. Without Elementor templates or add-ons, Hello offers fewer blog-specific conveniences than Astra, GeneratePress, or Twenty Twenty-Four. The apparent simplicity also hides a dependency: if the site's layout, archive logic, and content presentation live inside Elementor, switching away later requires real reconstruction.

Choose Hello for a builder-led operation

Hello works when the team has a reason to standardize on Elementor. It can support a highly customized portfolio, service site, or publication with a branded editorial shell, but it isn't the obvious choice for a minimal WordPress blog that should remain close to core functionality.

Audit mobile settings at the widget and template level. Elementor gives responsive controls, but editors can create inconsistent breakpoints, oversized sections, and decorative elements that make articles harder to read. Keep article templates simpler than marketing pages, and make sure core WordPress search, feeds, navigation, and empty states still have deliberate designs.

The theme itself is light. The finished website may not be, because the builder, widgets, animations, fonts, and third-party integrations determine the final payload.

8. Divi by Elegant Themes

Divi by Elegant Themes

Divi is a theme and visual builder ecosystem rather than a narrowly focused blog foundation. Its appeal is consistency. The Visual Builder, Theme Builder, layout packs, Divi AI options, and marketplace give a team one visual environment for creating branded pages, reusable sections, and promotional layouts.

That can accelerate design iteration for a creator who thinks visually. Divi Quick Sites and imported layout packs reduce the amount of blank-canvas work, while cloud storage for layouts and products such as Bloom and Monarch extend the ecosystem beyond page design. An unlimited-site license can also make sense for agencies or operators managing several properties.

The cost is structural dependence. Divi is heavier than minimalist themes, and the smoothest workflow assumes that the site remains inside the Divi ecosystem. Editors who only need to publish standard articles may find the visual layer more elaborate than necessary.

Where the builder earns its place

Divi is suitable when landing pages, conversion sections, email capture, and brand consistency matter as much as the archive. For a publication, keep the editorial template restrained and reserve advanced modules for the homepage or campaign pages. A long article shouldn't inherit the visual complexity of a sales page.

Test migration assumptions before launch. Export a layout, examine how content behaves outside the builder, and confirm that editors can publish without touching design settings. The builder's learning curve is manageable for a dedicated team, but it adds process and training requirements for occasional contributors.

Divi is a capable integrated system. It's not the best answer merely because its demo looks responsive.

9. Avada by ThemeFusion

Avada is a mature website builder built around its own visual tools. It offers live editing, layout, header and footer, mega-menu, and form builders, along with a large element library and importable demos. For a small business owner who wants a complete site assembled quickly, that breadth is the central attraction.

The theme supports a buy-once-per-site model with lifetime updates for each site license. Its performance wizard gives the operator controls for reducing unnecessary features, but the imported demo still needs review. Large demos can bring extra images, scripts, widgets, and layout components that a focused publication doesn't need.

Avada works best when a team wants a defined visual system instead of a loose collection of plugins. The documentation and long market history reduce the risk of adopting an abandoned tool, while the demo library can help non-technical owners reach a credible starting point.

Import less than you think you need

Start with the smallest relevant demo, then remove unused pages and elements before adding content. Check the homepage, archive, single post, search, 404, and “Nothing Found” screens on real devices. Don't assume the performance wizard fixes every issue created by oversized images, animations, or third-party scripts.

The one-site license also matters. Agencies or owners planning several sites must account for the single-use license model rather than treating the theme as a universal asset.

Avada is a reasonable choice when the integrated builder and mature documentation justify additional weight. It's a poor fit when the publication's needs are primarily semantic HTML, straightforward posts, open feeds, and minimal administration.

10. Twenty Twenty-Four

Twenty Twenty-Four

Twenty Twenty-Four is the standards-first option in this list. As the official default theme for WordPress 6.4, it was built for Full Site Editing, with the Site Editor, global styles, patterns, page templates, and core blocks forming the entire design model.

That matters for portability. The site doesn't need a commercial builder to create its basic structure, and editors work inside the WordPress editing system rather than a separate visual language. The theme is free and maintained by WordPress.org, which makes it a sensible baseline for a content-first publication that values fewer vendor dependencies.

It won't provide the same library of turn-key demos as commercial themes. Customization depends on learning Full Site Editing, including template parts, styles, patterns, navigation, and block settings. That learning curve is real, but so is the benefit of understanding the system that stores and renders the site.

For a publication such as Read More Info, start by studying WordPress blog layouts for content sites and then build only the patterns the editorial workflow needs. Keep the homepage, post template, archive, search, and empty state consistent rather than adding decorative sections just because the editor makes them possible.

Why it's a strong long-term baseline

Twenty Twenty-Four works entirely with core blocks and is responsive and accessible by default according to its positioning as a WordPress default theme. Still, test the final site. Accessibility and responsive behavior can be weakened by custom blocks, poor color choices, oversized media, or incompatible plugins.

WordPress recommends testing themes in different browsers and screen widths, and that should include keyboard navigation, zoom, rotation, touch interaction, and screen-reader landmarks. A theme that preserves readable content without a builder lock-in is often easier to maintain than a more impressive demo.

Top 10 Responsive WordPress Theme Comparison

ThemeCore featuresUX & Performance (★)Price / Value (💰)Best for (👥)Standout (✨ / 🏆)
Astra (Brainstorm Force)Performance-first, header/footer builder, large starter library, Gutenberg/Elementor★★★★, Fast, clean reading💰💰 Free core; Pro addon👥 Bloggers & sites planning expansion✨Large starter library; 🏆Big community & docs
GeneratePressMinimal, GP Premium theme builder, GenerateBlocks integration★★★★★, Extremely fast, CWW-friendly💰💰 Free core; Premium for builder👥 Performance-focused blogs & developers✨Tight block integration; 🏆Proven stability
Kadence Theme (Nexcess)Blocks-first, global controls, 200+ templates, dynamic add-ons★★★★, Polished typography, pro-ready💰💰💰 Freemium; bundles under annual plans👥 Growing sites, membership/commerce✨All-in-one growth tooling; 🏆Quick professional look
Neve (Themeisle)Multiple blog layouts, 110+ starters, performance module★★★★, Mobile-first, attractive templates💰💰 Freemium; Pro templates/cloud👥 Bloggers & magazines wanting quick setup✨Many starters; good WooCommerce/LMS support
Blocksy (CreativeThemes)Customizer-driven, header/footer builder, blog extras, WooCommerce★★★★, Fast, user-friendly UI💰💰 Feature-rich free; Pro add-ons👥 Non-technical users wanting flexibility✨Feature-rich free tier; 🏆Clear UI
OceanWPExtensive Customizer controls, demos, Ocean Extra plugin★★★, Very configurable; can bloat💰💰 Freemium; Pro bundles👥 Elementor users & highly configurable blogs✨Fine-grained control; large demo library
Hello (Elementor)Ultra-minimal blank canvas, tiny footprint, Elementor Theme Builder★★★, Extremely lightweight; minimal niceties💰 Free👥 Elementor-driven custom designs✨Zero-cost canvas for Elementor
Divi (Elegant Themes)Visual Builder, 300+ packs, Divi AI, unlimited sites/license★★★★, Powerful visual editing; heavier💰💰💰 Premium (annual/lifetime)👥 Designers/agencies needing visual tools✨Huge asset ecosystem; 🏆Integrated visual builder
Avada (ThemeFusion)Live Visual Builder, 110+ demos, many elements, lifetime updates★★★, Mature, demo-heavy if overused💰💰 One-time per-site ThemeForest license👥 Users wanting many demo starters & buy-once✨Massive demo library; lifetime updates
Twenty Twenty-Four (WP default)Full Site Editing, global styles, core blocks, responsive★★★★, Standards-first, accessible💰 Free (WordPress.org)👥 Content-first blogs avoiding vendor lock-in✨Core-driven FSE; 🏆Official WordPress theme

Choose the Foundation You Can Maintain

There isn't one universal winner. The right responsive template for website use depends on who will edit the site, how much design control the publication needs, and whether the team can maintain the resulting builder and plugin stack.

Choose Twenty Twenty-Four or GeneratePress for a standards-first, lean publication. Twenty Twenty-Four keeps the site close to WordPress core and Full Site Editing, while GeneratePress offers a more configurable performance-focused foundation for teams comfortable adding GenerateBlocks or premium controls. Both choices make sense when readable articles, predictable archives, semantic structure, and low maintenance matter more than a large demo library.

Choose Astra, Neve, or Blocksy when you want a faster visual setup with room to grow. Astra is broadly compatible and adaptable, Neve gets an attractive blog online quickly, and Blocksy provides a particularly capable interface for creators who want richer blog and commerce options. In each case, enable only the modules that support the publication's actual workflow.

Choose Hello when Elementor is already the operating model. It's a clean base for a custom builder-led site, but it isn't a complete editorial experience by itself. Choose Divi or Avada when an integrated builder ecosystem is worth the additional weight, training, licensing, and migration considerations.

Before importing a full demo, install one candidate on a test site. Review the homepage, archive, post, search, and empty-state behavior at phone and desktop widths. Then verify:

  • RSS links: Confirm the site-wide feed and comments feed remain available and discoverable. WordPress documents both /feed/ and /comments/feed/ as standard endpoints in its feed guidance.
  • Typography: Check line length, heading wrapping, link visibility, and readability when the browser is zoomed.
  • Navigation: Test keyboard focus, touch targets, menu collapse, and the path back to the archive.
  • Image sizing: Publish different image dimensions and confirm that small screens don't download or display unnecessarily oversized media.
  • Performance: Audit the actual templates after adding fonts, analytics, embeds, plugins, and editorial images.
  • Portability: Determine which content remains usable if the theme or builder is removed.

Responsive design has moved from an optional enhancement to a baseline expectation. Earlier responsive design theory centered on fluid grids, flexible images, and media queries in Ethan Marcotte's influential 2010 article, while a later dataset reported responsive techniques on 62.5% of websites worldwide in 2023, media queries on 94% of the top 1,000 websites, and adoption on 81% of Fortune 500 websites that year dataset summary. The figures explain the standard's reach, but they don't choose a theme for you.

The practical quality bar is higher than visual resizing. Guidance on responsive accessibility emphasizes preventing horizontal scrolling, preserving legible text, supporting keyboard and touch navigation, and avoiding fixed-width elements responsive accessibility guidance. Mobile performance matters too. One UX summary reports that 53% of mobile visitors leave a page when it takes longer than three seconds to load, while 74% are more likely to return to a mobile-friendly site, 67% are more likely to buy from one, and 52% say a poor mobile experience makes them less likely to engage with a company UX statistics summary. Those figures are benchmarks, not guarantees, so test your own site rather than borrowing confidence from a demo.

The best responsive template for website use is the one that keeps articles readable, archives discoverable, feeds accessible, and maintenance manageable after launch. Pick the foundation your team can still understand when the first redesign, plugin conflict, or content spike arrives.


Read More Info publishes straightforward WordPress articles for general readers, with responsive reading, on-site search, and open RSS feeds for site updates and comments. Visit Read More Info to see a lean content publication in practice and use it as a reference while evaluating your own responsive template.

10 Feed Reader Firefox Options Compared

Most advice about a feed reader Firefox setup starts with the extension list. That's backwards. The right choice depends on whether you want browser-local storage, synchronized access across devices, aggressive filtering, bookmark-style browsing, or a reader you can own and maintain yourself. The practical comparison is setup friction, feed discovery, full-text handling, refresh behavior, privacy, exportability, and how much maintenance you're willing to carry.

Read More Info gives a useful test case for any feed reader Firefox workflow because it exposes both a site feed and a comments feed, so you can compare article updates and discussion updates side by side. Test with the main Read More Info feed and the comments feed. If you want a quick broader benchmark for reader selection, the smart RSS reader picks roundup can help frame the trade-offs before you install anything.

Table of Contents

1. Feedbro

Feedbro is the strongest choice if you want a full reader living inside Firefox instead of a separate service. Its page detection, standalone RSS, Atom, and RDF handling, plus a rule engine for filtering, tagging, and notifications, make it feel closer to a local workflow hub than a simple subscription list. The trade-off is obvious, your data follows the browser profile, not a cloud account.

Feedbro

Feedbro's built-in full-text conversion matters when feeds are truncated. If a publisher only exposes summaries, the extension can often reconstruct enough readable content to keep you from jumping back to the site. That's useful in real reading sessions because it keeps the workflow inside Firefox, especially when you're skimming many sources at once.

Practical rule: choose Feedbro when you care more about control than portability. Export and backups become part of the job, because the data is local and tied to the Firefox profile.

Why it works well

  • No separate account: you can subscribe and read without signing into another service.
  • Offline-friendly after fetch: once articles are pulled in, you can keep reading without depending on a live connection.
  • Useful for power users: the filtering and notification rules are far more capable than the average browser add-on.

Where it falls short

  • Profile dependence: if you move browsers or profiles, you need to manage exports.
  • Update delays can happen: add-ons still live under store review cycles, so fixes and improvements don't always land instantly.

For teams or solo readers who like local ownership and don't mind a bit of housekeeping, Feedbro is one of the clearest fits. The Read More Info blog is a good place to test how it handles a normal WordPress feed and a comment stream in the same browser.

2. Feeder

Feeder is the polished option when the feed reader Firefox experience needs to sync cleanly across devices. The browser extension is only part of the product, because the true value is in the web and mobile apps that keep unread items, dashboards, and notifications aligned. That matters if you switch from desktop reading to phone reading without wanting to reconfigure everything.

Feeder

The platform's plan structure is a major decision factor. Feeder publishes a clear pricing grid, and the free plan has limits on feed count and update speed, while faster polling and heavier usage sit on paid tiers. That makes it easier to evaluate than vague freemium products, but it also means the free experience is intentionally bounded.

A better way to think about Feeder is as a synchronized reading system, not just a Firefox add-on. You get unread counters, quick-post lists, rules, and email summaries, which is useful if you treat feeds as a daily queue instead of an archive you occasionally browse. For people who rely on regular checks rather than deep local curation, that workflow is smooth.

Best fit

  • Cross-device readers: if you expect the same subscriptions on desktop and mobile.
  • Notification-driven monitoring: if feed updates need to reach you outside the browser.
  • Users who want transparency: the feature grid makes plan boundaries easy to understand.

Less ideal

  • Free-tier constraints: capped feed counts and slower refresh can get in the way as your list grows.
  • Less ownership than local tools: your reading experience lives inside a service rather than your own browser data.

If your priority is convenience and sync, Feeder is easier to live with than a local-only extension. If your priority is data custody, it's not the first pick.

3. Smart RSS Reader

Smart RSS Reader is the minimalist answer for people who want a lightweight feed reader Firefox setup without a cloud layer. It runs in a single tab, keeps the interface simple, and leans on local storage with OPML import and export. That makes it feel closer to a quiet utility than a platform.

Smart RSS Reader

The main advantage is speed through restraint. You open it, load feeds, and read. There's no heavy dashboard to learn, and that simplicity matters when you only want a local inbox for articles and don't need automation, sharing layers, or a team workspace.

It's the kind of reader that works best when you want the browser to stay a browser.

There's a real ownership angle here too. Because it stores feeds locally and supports OPML, you can move subscriptions in and out without building your workflow around a vendor account. That's attractive for readers who like to keep things portable but don't want to run a server.

Good reasons to use it

  • Simple local use: low friction and easy to understand.
  • No account required: fewer moving parts and fewer privacy trade-offs.
  • OPML support: subscription portability stays practical.

Main limitations

  • No cloud sync out of the box: device-to-device continuity is up to you.
  • Limited future development flags: that means you should treat it as a simple utility, not a long-term platform bet.

If you want the least complicated Firefox-native reader that still respects exportability, Smart RSS Reader is a smart stop. It also fits the standard blog syndication workflow cleanly, which makes it easy to test against ordinary WordPress feeds before committing to something bigger. For a basic publishing reference point, see this guide to blog syndication.

4. Livemarks

Livemarks is for people who never really liked dedicated readers in the first place. It restores the old bookmark-folder style of feed reading, so subscriptions appear where Firefox users already expect to find site collections. That makes it less of a new app and more of a familiar browsing pattern.

Livemarks

This model has a real advantage when your feeds are mostly a handful of sites you check often. You don't need a separate reading pane, a tagging system, or a notification engine if you mainly want bookmark-style folders that update. It also works naturally with any site that exposes a feed, including WordPress sites.

The trade-off is feature depth. Livemarks is lightweight by design, but that also means it stops short of the richer reader behaviors many power users expect. There's no serious rule system, no full-text extraction layer, and no offline cache to help with longer sessions away from the site.

Use it when

  • You prefer bookmarks to dashboards: feed reading becomes part of browsing, not a separate task.
  • You want almost no setup: it's straightforward to understand immediately.
  • You only need basic refresh behavior: not every subscription list needs automation.

Skip it when

  • You want advanced filtering: it won't replace a dedicated reader.
  • You need strong offline reading: it's not built for deep local caching.

Livemarks is a good fit for low-maintenance readers and for people who miss browser-native syndication. It doesn't try to be the best reader, it tries to be the least intrusive one.

5. Inoreader

Inoreader is the heavy-duty choice for readers who want automation, discovery, and content handling in the same place. It does more than aggregate feeds, because it can prioritize items through filters, rules, and full-content loading, while also supporting newsletter-to-RSS and Google News alert workflows. That mix makes it useful for people who read at scale.

Inoreader

The strongest part of Inoreader is how much it can absorb before your reading process breaks. If you're following many sources, need one place for newsletters, or want rules that sort by topic and source behavior, it gives you enough controls to build a real intake system. That's especially useful if your feed reader is also part of your research or monitoring stack.

Its weakness is the same thing that makes it powerful. A lot of the advanced capability lives behind paid plans, and the free tier is intentionally narrower. That doesn't make the product weak, but it does mean the best version of Inoreader is a subscription decision, not just a browser install.

Use it when your priorities are:

  • Automation: rules, filters, and content handling matter more than minimalism.
  • Cross-platform access: you want the same workflow on desktop and mobile.
  • Import/export discipline: you need a reader that can move subscriptions cleanly.

The extra value shows up when you read large volumes and want less manual triage. If your workflow is mostly simple subscription reading, Inoreader can feel heavier than necessary. But if you want the reader to do more of the sorting for you, it earns its place quickly. For WordPress publishers who care about presentation and syndication alongside reader behavior, the Read More Info WordPress layout guide gives a useful publishing-side companion.

6. Feedly

Feedly is the better fit when you want a hosted reader that stays out of the way until you need more control. It is easy to set up, works across devices, and adds keyword tracking and integrations without forcing a local extension workflow.

Feedly

That makes it useful for people who want one place for routine reading and a path to more advanced filtering later. The trade-off is ownership. Your reading setup lives in Feedly's cloud, so it is less private and less self-directed than a Firefox-only add-on or a self-hosted aggregator.

Feedly also scales better than many simple readers. Individual users can keep it lightweight, while teams can use the higher tiers for faster polling, power search, and AI-assisted curation. Those features matter if you read at volume or need shared workflows. If you only want a browser-side subscription list, they can feel like overhead.

Decision point: choose Feedly if you want convenience, sync, and a managed platform. Choose a local extension if you want the reader to stay inside Firefox.

What it does well:

  • Clean onboarding: it is quick to start using.
  • Cross-platform reading: desktop and mobile stay aligned.
  • Team and integration support: useful when the reader sits inside a wider workflow.

What it asks in return:

  • Plan awareness: the better features sit higher in the pricing tiers.
  • Less local control: your subscriptions and reading history live in the cloud rather than in Firefox.
  • Publishing-side context: if you want to think about syndication and layout together, the Read More Info guide to WordPress blog layouts is a useful companion.

Feedly fits readers who want polish and reach more than tinkering and local storage. Test it against the Read More Info comments feed first. If the AI curation tiers are the part you need, the upgrade decision will be clear.

7. NewsBlur

NewsBlur is the flexible reader for people who want a little more control over what surfaces first. Its Intelligence system learns from author, tag, and title signals, so you can train the reader toward the content that matters most. That makes it particularly good for readers with mixed interests and noisy subscription lists.

The hosted product is only part of the story. NewsBlur also offers an open-source server you can self-host, which gives technically inclined users a real ownership path. That matters because the same product can serve both a convenience reader and a personal infrastructure project.

There's also a broader reading angle here. NewsBlur can follow web pages even when a feed isn't available, which helps when sites don't expose clean RSS endpoints. That widens the range of pages you can keep under one roof, although some advanced capabilities sit behind premium pricing.

Why people choose it

  • Training-based prioritization: useful when one list has many different subjects.
  • Hosted or self-hosted: you can choose convenience or control.
  • Web-page following: helpful when a site doesn't publish a usable feed.

Why people pass

  • Premium boundaries: some features are gated.
  • Less immediate than minimalist tools: the learning layer adds complexity.

NewsBlur makes the most sense for readers who are willing to teach the system what matters. If you want a browser-native, no-frills reader, this isn't the simplest path. If you want a reader that adapts to your habits, it's one of the more interesting options.

8. BazQux Reader

BazQux Reader is the fast, no-nonsense choice for people who care more about reading than about visual flourish. It's a web reader with strong full-text extraction, good keyboard navigation, and smart filtering. The interface feels tuned for solo use, especially if you read a lot and want less friction per item.

The product's value comes through in the details. Full-text conversion helps with partial feeds, keyboard shortcuts keep navigation quick, and its comment support on some sites adds a useful layer for readers who follow discussion as well as posts. That makes it especially appealing if your feed habits are more analytical than social.

BazQux also keeps the business model simple. There's a trial, then it's paid. That can be a drawback if you want a perpetual free tier, but it also means the product doesn't try to hide its boundaries. For some buyers, that's easier to trust than a complicated freemium ladder.

BazQux feels like a tool built by people who actually read feeds every day, not by people trying to attach feed reading to a bigger platform pitch.

Strong points:

  • Fast interface: good for high-volume reading sessions.
  • Good typography and shortcuts: the reading experience stays efficient.
  • Transparent paid model: you know what you're paying for.

Weak points:

  • No permanent free plan: it's a paid product after the trial.
  • Smaller service footprint: it's not trying to be an all-purpose suite.

Use BazQux when you want a responsive reader that stays out of your way. It's a good fit for individual users who value speed and clarity over ecosystem depth.

9. Miniflux

Miniflux is the cleanest answer if privacy and ownership are the main decision factors. It's self-hostable, has an official hosted option, and keeps the interface deliberately sparse. The design is opinionated in a useful way, because it avoids the clutter that turns reading into administration.

Miniflux

That simplicity is not a lack of features, it's a choice about what belongs in a reader. Miniflux supports standard APIs for third-party apps, so it can act as a backend for a broader reading setup if you want to keep your interface options open. That's a strong pattern for people who like minimal web UIs but still want mobile or alternate clients.

The hosted plan is attractive for readers who want ownership without server administration. The self-hosted route is better if you want full control, but it does add maintenance work and the responsibility to keep the service running. That's a worthwhile trade if data custody matters to you, but it's not free in operational terms.

What stands out

  • Privacy-first design: minimal tracking and a restrained interface.
  • Hosted or self-hosted: choose based on maintenance tolerance.
  • API support: useful if you want multiple clients around the same backend.

What to expect

  • Less visual polish than big cloud readers: the interface is built for utility.
  • Some speed and refresh trade-offs on hosted use: if you need more control, self-hosting may be the better path.

Miniflux is one of the best choices when you want a reader that behaves like infrastructure, not a productized social app. It rewards people who know exactly what they want.

10. FreshRSS

FreshRSS is the most obvious pick when self-hosting is part of the plan. It's open source, multi-user, extensible, and built to run on modest hosting, which makes it practical for readers who want control without needing a heavy server stack. It also supports OPML import and export, so migration stays manageable.

The standout feature is flexibility. FreshRSS can use WebSub push and can scrape JSON or HTML through XPath for sites without clean feeds. That makes it useful in cases where a publisher's syndication is incomplete or inconsistent, and it broadens the number of sources you can keep under one umbrella.

Its biggest trade-off is also clear. You own the setup, the updates, and the upkeep. If that sounds like work, because it is. But for people who want data control, community-driven software, and a reader that can live on their own server, that work is the point.

Where FreshRSS fits

  • Control over data: the service is yours.
  • Flexible ingestion: feeds, push, and scraping can coexist.
  • Light hosting requirements: it can run on modest infrastructure.

Where it costs you

  • Setup and maintenance: you're responsible for the system.
  • No official hosted tier: third-party hosting is outside the core project.

FreshRSS is the best match for readers who think in terms of infrastructure, not just apps. If you want your reader to be part of your own stack, it's hard to beat.

Top 10 Firefox Feed Readers, Feature Comparison

ReaderKey features ✨UX / Quality ★Price / Value 💰Target audience 👥USP / Notes 🏆
FeedbroStandalone in‑Firefox reader; rule engine; full‑text; offline★★★★💰 Free (local storage)👥 Firefox users wanting local/offline🏆 Powerful rule engine; no cloud account
FeederExtension + web/mobile; rules, dashboards; faster polling tiers★★★★💰 Freemium (caps); Pro for faster refresh👥 Cross‑device users needing sync & alerts🏆 Smooth sync & clear plan limits
Smart RSS ReaderLightweight single‑tab reader; folders/tags; OPML support★★★★💰 Free, open‑source👥 Minimalists who want a local, simple reader🏆 MIT‑licensed, no account required
LivemarksFeeds as bookmark folders; integrates with bookmarks UI★★★💰 Free👥 Users who prefer bookmark‑style browsing🏆 Restores classic Live Bookmarks model
InoreaderFilters, automation, AI summaries, newsletter→RSS, mobile apps★★★★★💰 Freemium; Pro for automation/AI👥 Power readers & automation-heavy workflows🏆 Deep automation and discovery tools
FeedlyCloud reader with integrations; Pro+ AI curation & team features★★★★★💰 Freemium; Pro / Pro+ (paid tiers)👥 Individuals & teams wanting polished apps🏆 Strong ecosystem & AI curation (Pro+)
NewsBlurIntelligence training, full‑text, follow web pages, self‑hostable★★★★💰 Freemium; premium for advanced; self‑host option👥 Users wanting flexibility & self‑hosting🏆 Training filters + self‑host option
BazQux ReaderExcellent full‑text extraction; keyboard nav; comments support★★★★💰 Paid after 30‑day trial👥 Solo users who want speed & good typography🏆 Fast, efficient interface and extraction
MinifluxMinimal, privacy‑focused; self‑host or low‑cost hosted plan; APIs★★★★💰 Low‑cost hosted / self‑host👥 Privacy‑conscious minimalists🏆 Minimal tracking and API compatibility
FreshRSSSelf‑hosted aggregator; scraping/WebSub; extensions ecosystem★★★★💰 Free (self‑host; hosting cost applies)👥 Self‑hosters seeking full control🏆 AGPL open‑source, extensible and lightweight

Choose the Reader You Will Actually Maintain

The best feed reader Firefox choice is the one you'll keep using after the novelty wears off. Choose Feedbro or Smart RSS Reader if you want local Firefox reading with the fewest moving parts. Choose Livemarks if bookmark-based browsing feels more natural than a dedicated reader interface. Choose Feeder if synchronized access across devices matters more than local data ownership.

If you need discovery and automation, Inoreader and Feedly are the strongest cloud-first options, especially when rules, integrations, and broader workflows matter. If your reading style depends on prioritization or specialized handling, NewsBlur and BazQux Reader make more sense than generic readers. If ownership and self-hosting are the deciding factors, Miniflux and FreshRSS are the serious contenders.

A practical setup sequence avoids most regret. Subscribe to the main Read More Info feed, optionally add the comments feed, then import or export OPML so you can move subscriptions cleanly if the tool doesn't fit. After that, confirm refresh behavior and full-text handling on a handful of real sites, and only then decide whether you need backups or server maintenance before moving a larger feed collection.


Read More Info publishes straightforward WordPress updates that are easy to test in any RSS workflow, which makes it a useful site for checking feed behavior, comments tracking, and search-driven reading. If you're comparing feed reader Firefox options against a real publishing setup, visit Read More Info and use its feeds to see which reader matches the way you read.

Search Site for Word

You remember the phrase, but not the page. You type it into a site search box, get nothing useful, switch to Ctrl+F, and end up scrolling through the wrong article while the browser insists there's no match. That's the common failure mode behind search site for word. The problem isn't just finding text, it's choosing the right search path for the scope you need.

Table of Contents

Why Searching a Site for a Word Is Harder Than It Looks

A single remembered phrase can live in three different places at once, and each one needs a different tool. If the text is on the page you've already opened, browser find is the fastest option. If it's somewhere on the domain but you don't know where, Google's site: operator is the better route. If the content sits inside the site's own database, WordPress search is the built-in path.

A diagram explaining why searching a website for a specific word is difficult for users.

Three tools, three scopes

Browser find only scans what the browser has already rendered on the current page. That's why it's brilliant for a quick in-page lookup and useless for finding a word buried elsewhere on the site. Google search looks across the web index, but only for pages it has crawled. WordPress search queries the content your site owner has stored and exposed through the theme and database.

The practical mistake is treating them as interchangeable. A user will often start with the site search box because it feels “official,” then move to Ctrl+F because it feels immediate, then give up before trying a domain search. When a query fails, the failure usually says more about scope than about the missing word itself.

Practical rule: start with the narrowest tool that can possibly work, then widen the scope only when the first path comes up empty.

The same phrase can also fail because the page uses different wording. A post about “account recovery” might never say “reset password,” even though a human would treat those as the same idea. That's why the tool choice matters as much as the search term.

Using Browser Find to Search a Page for a Word

Browser find is the cleanest move when the page is already open and you just need to locate a word fast. On Windows and Linux, press Ctrl+F. On macOS, press Cmd+F. The browser opens a find bar, usually at the top or bottom of the window, and you can jump straight to the match.

Type the word once, then use Enter or the down arrow to move forward through each occurrence. Shift+Enter moves backward. That makes it ideal for checking whether a term appears multiple times in a long article, a documentation page, or a product page with dense copy.

Screenshot from https://example.com/screenshots/browser-find-bar.png

When Ctrl+F misses what you expect

Browser find can miss content that hasn't been rendered yet. Collapsed accordions, iframes, shadow DOM elements, and some dynamically loaded sections are common blind spots. If the page loads content only after scrolling or clicking, the browser may not search it until that content exists in the DOM.

Case sensitivity is usually off, which helps in real use. Whole-word matching is also off, so partial substrings can match inside longer words. That's useful when you're not sure about spelling, but it can also create false positives if you're searching for a short fragment.

A simple trick solves a lot of these misses. Open the page in reader mode or print preview, then try Ctrl+F again. Those views often flatten the layout and expose text that a live page hides behind scripts.

The key is to treat browser find as a page-local scanner, not a site-wide search engine. It's fast, reliable, and brutally limited by design.

If the word is visible on the page but Ctrl+F can't find it, the problem is usually rendering, not spelling.

Searching a Whole Site for a Word With Google Operators

When the word lives somewhere on a site but you don't know which page, Google operators are the most efficient route. The basic pattern is simple: site:example.com followed by the word or phrase. If you want an exact phrase, put it in quotes. So site:example.com "concrete resurfacing" only returns pages that contain that exact wording.

You can narrow the hunt further with intitle: and inurl:. site:example.com intitle:"pricing" is useful when you want a pricing page. site:example.com inurl:blog "keyword" is better when you want posts instead of product pages. If you want to exclude a section, add a minus sign, like site:example.com -inurl:forum.

Query patterns that actually help

OperatorWhat It DoesExample
site:Limits results to one domainsite:example.com word
QuotesForces an exact phrase matchsite:example.com "concrete resurfacing"
intitle:Looks for the term in the page titlesite:example.com intitle:"pricing"
inurl:Looks for the term in the URLsite:example.com inurl:blog keyword
Minus signExcludes a path or termsite:example.com -inurl:forum

The weakness is index coverage, not syntax. If a page hasn't been crawled yet, is blocked, or is set to noindex, Google won't return it no matter how clever the query is. That makes Google excellent for discovering published content and unreliable for fresh or hidden content.

For broader keyword work, tools like Google Keyword Planner can still help with baseline ideas, but its range-based data is less precise than exact-volume tools. If you're shaping content around search intent rather than just page discovery, that difference matters.

Using WordPress Site Search the Right Way

WordPress search is the right tool when you want the site's own database to do the work. On a standard setup, you can trigger it with /?s=yourword, a search widget, or a search block in the header. If the header search is missing, the footer shortcut on a straightforward WordPress site is often the quickest route back in.

The search results usually sort by date, not by relevance, so the best match can sit lower than you expect. That's why a result list can look “wrong” even when the word is present. If you're searching for a phrase, try entering it exactly as written, with quotes if the theme and search setup honor them.

Where native WordPress search is useful and where it isn't

Native WordPress search is fine for blog archives, simple publishing sites, and quick checks inside the public site. It's weaker when the content lives in custom fields, taxonomies, PDFs, or other data the stock loop doesn't index well. In those cases, a plugin like SearchWP or Relevanssi usually gives you better coverage.

Empty queries can behave differently depending on the theme. Some setups return all posts, while others show a blank page or a “Nothing Found” state. If you run a site like the one documented in how to create a WordPress blog, the search experience should be tested from the header, the widget, and any fallback footer link so visitors don't hit a dead end.

WordPress search is best when the site is self-contained and you want controlled discovery inside that publishing system. It's not the best answer when you're trying to approximate Google inside the site.

Why Site Search Quietly Fails for Natural Language Queries

Users don't type keywords anymore, they type questions. A query like “how do I reset my password” feels natural to the user, but a basic WordPress search often breaks that sentence into separate terms and expects the page to contain all of them in a useful way. That's why conversational queries can return nothing even when the answer exists.

A good technical primer on natural language processing, including how systems interpret meaning instead of raw keywords, is how SupportGPT uses NLP. That distinction matters because site search usually doesn't understand synonyms, intent, or phrasing the way a person does.

Keyword matching versus intent matching

WordPress's default behavior is closer to a keyword filter than a conversation engine. It can find exact or near-exact terms, but it struggles when a visitor says “change” and the article says “reset,” or when a page answers the question without repeating the question's wording. Google tends to do better here because its index is built to interpret broader relevance.

That's why native site search often feels fine for product names, article titles, and short labels, then falls apart on real questions. The more conversational the query gets, the more visible the gap becomes. If the site doesn't expand synonyms or understand intent, users will think the content is missing.

The failure isn't that the content doesn't exist. The failure is that the search box can't recognize how a human would ask for it.

The fix is usually structural, not magical. Better titles, clearer tags, and more deliberate internal indexing beat raw content volume almost every time.

Choosing the Right Method for the Job

Start with scope, then choose the tool. If you already have the page open, use browser find. If you need to search the domain, use Google operators. If you need to search the site's own content database, use WordPress search.

MethodBest ForLimitations
Browser FindWords on a page you're already viewingOnly sees rendered content on the current page
Google OperatorsFinding a word or phrase across a whole domainOnly works on indexed pages
WordPress SearchSearching the site's own posts and archivesOften weak on relevance and conversational queries

A practical decision tree is simple. If the text is visible, start local. If the page is unknown, search the domain. If the content is inside your own WordPress archive and Google isn't helping, use the site search or improve it. For a deeper layout-and-discovery mindset, the structure notes in best WordPress blog layouts help because search gets easier when the information hierarchy is cleaner.

Teams that want to measure search quality rather than guess at it should look at AI search analytics for startups. Good search isn't just about returning results, it's about seeing which queries are failing, which terms are drifting, and where users are giving up.

Troubleshooting When Nothing Comes Back

When every method fails, don't assume the word doesn't exist. First, check spelling and try a close variant. If you searched for the exact plural but the site uses the singular, WordPress may miss it because the stock search is blunt about word forms. Then switch to Google with a wider site: query and no quotes to see whether the page is indexed at all.

Quick fixes that separate the failure modes

  • Check the path: Use a domain-scoped Google search to see whether the page exists in the index, especially if the content is new or hidden.
  • Look for a different entry point: If the header search is missing, a footer shortcut or sidebar widget may be the only usable on-site route.
  • Broaden the wording: Remove quotes, try a stem variant, or search for a related phrase rather than the exact sentence.
  • Test for exclusions: If the page exists but never surfaces, it may be blocked by a plugin setting, marked noindex, or excluded from search.
  • Refresh and retry: Clear cache, reload, and test again before assuming the result is permanent.

If you're dealing with a dead-end inside a content site, the site's own archive can still reveal patterns. The post list at Read More Info blog is a good reminder that content discovery only works when the structure is predictable, the search entry point is visible, and the indexing rules are consistent.

The best fix is usually to reduce ambiguity before users start searching. Clear labels, cleaner titles, and better internal search behavior prevent most of the “nothing found” moments that waste time.


If you want clearer search paths, stronger content structure, and a WordPress site that's easier to explore, visit Read More Info. It's built for readers who need straightforward discovery, not guesswork, and this topic sits right at that intersection.